slopfence:检测 AI 编码助手遗留垃圾代码的质量门禁工具
syedmuhdahmad/slopfence
slopfence 是一款针对 AI 辅助代码的确定性质量门禁工具,可检出 AI 编码助手留下的幻觉包、无意义测试、占位桩、重复辅助函数、被吞掉的异常和残留聊天文本。


A fast, deterministic quality gate for AI-assisted code.
slopfence finds the junk that AI coding assistants leave behind (hallucinated packages, tests that test nothing, placeholder stubs, duplicate helpers, swallowed errors and leftover chat text) before it gets merged.
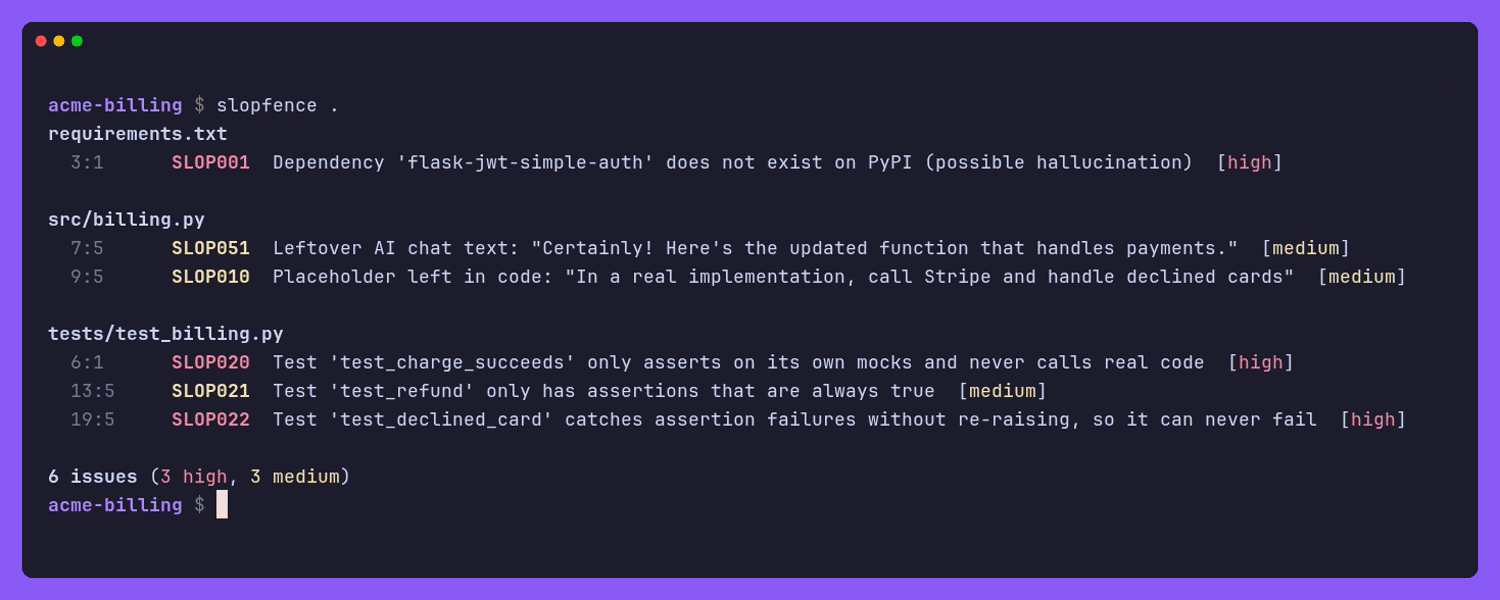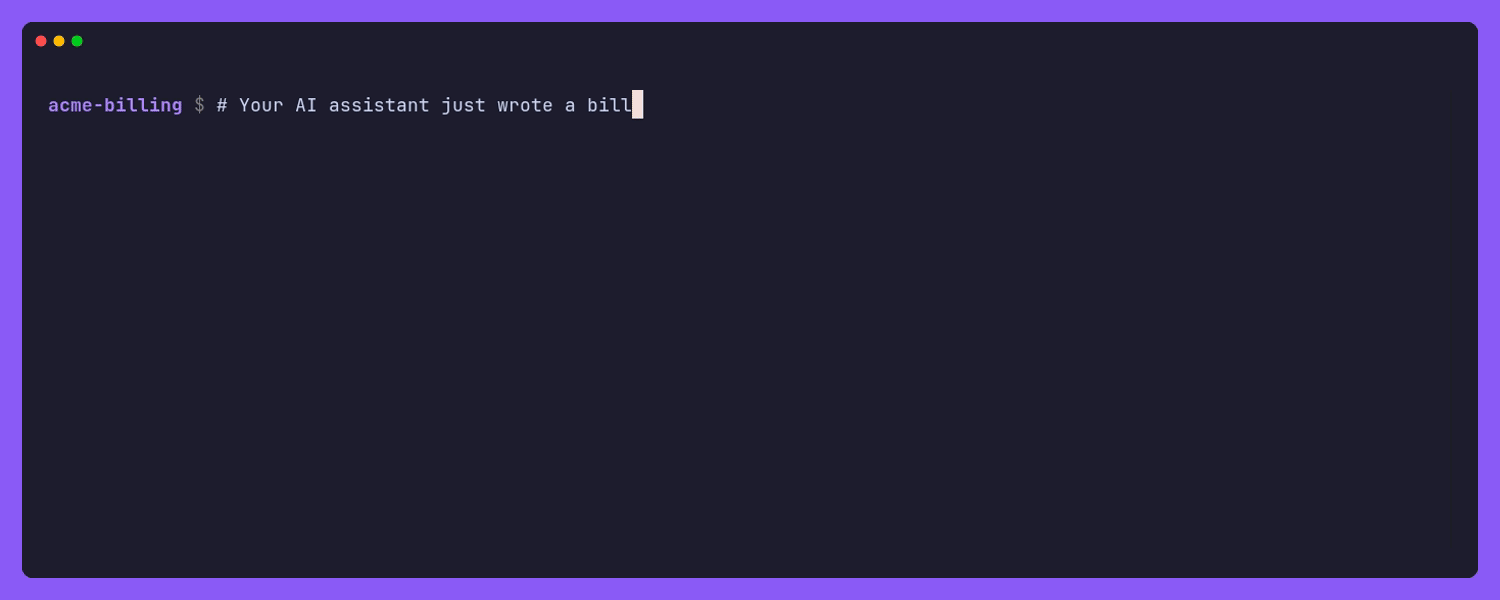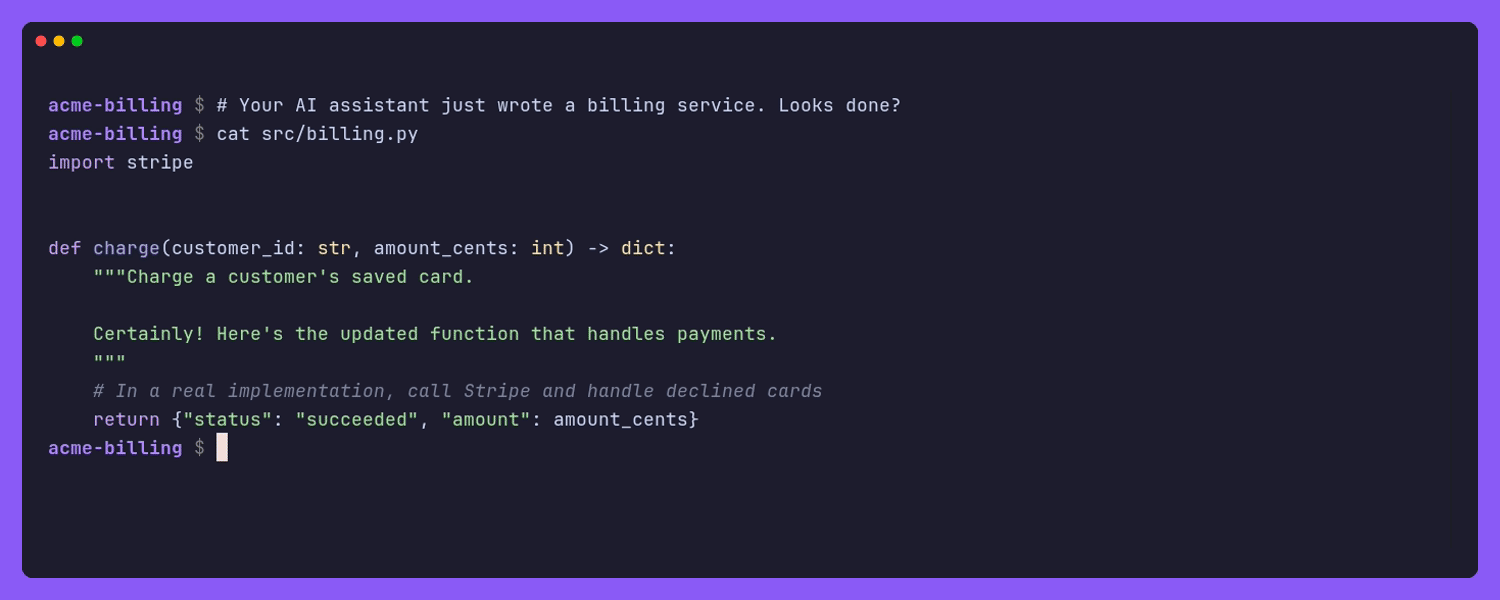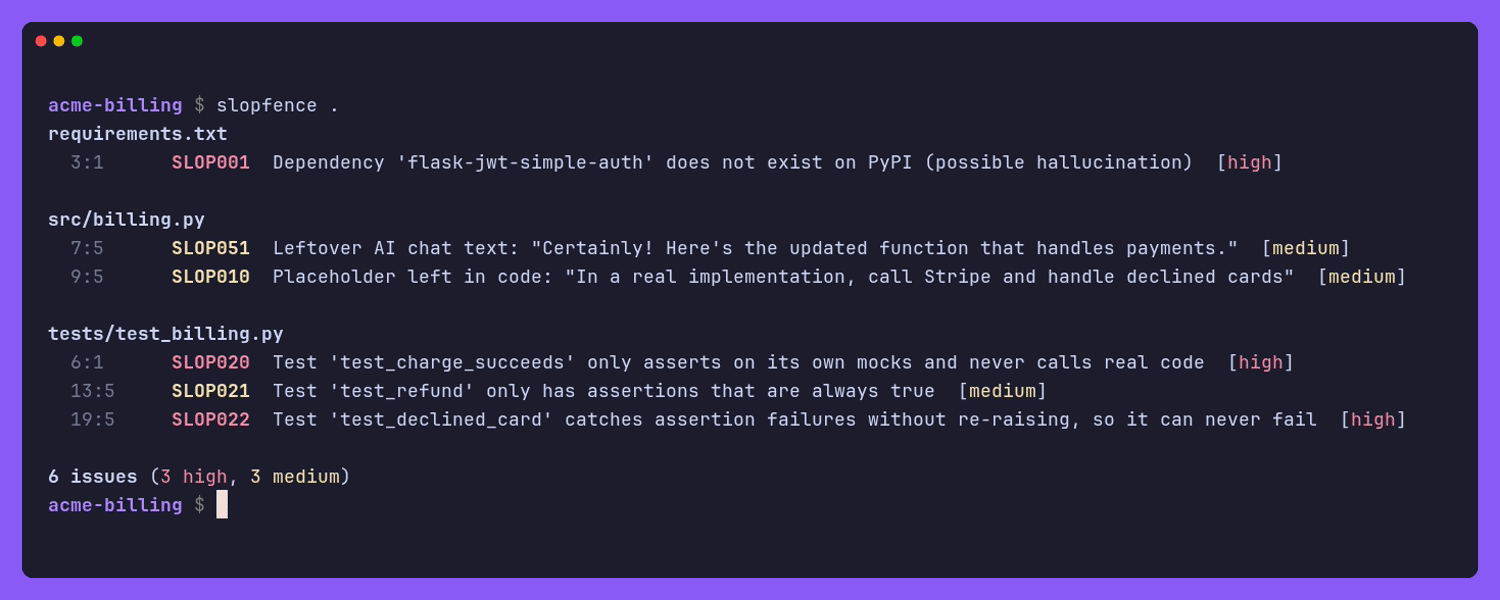
🚧 Status: alpha (v0.2, Python only). Nine detectors work, each tuned against 20,000+ files of real-world code for false positives. Expect rough edges. Feedback is very welcome. See Contributing.
Quick start
pip install slopfence
Or run it without installing, using uv or pipx:
uvx slopfence .
pipx run slopfence .
Check a project:
slopfence .Check only what your branch changed (ideal for pull requests):
slopfence --diff main
Options
| Option | What it does |
|---|---|
--diff REF |
Only report issues on lines changed since REF (plus new untracked files) |
--format text|json|sarif |
Output format. SARIF shows findings inline on GitHub pull requests |
-o, --output FILE |
Write the report to a file |
--offline |
Make no network requests (disables SLOP001) |
--check-imports / --no-check-imports |
Also look up unknown imports in your source code and notebooks on PyPI. Off by default, because it sends those names to pypi.org (see What slopfence sends over the network) |
--select / --ignore |
Comma-separated rule IDs to run or skip, e.g. --ignore SLOP051 |
--exclude |
Comma-separated paths or globs to skip, e.g. --exclude migrations,*_pb2.py |
--known-packages |
Comma-separated private package names or globs that SLOP001 must accept, e.g. --known-packages corp-* |
--detect-private-index / --no-detect-private-index |
Skip PyPI lookups when pip or uv is set up with a private index (on by default). Turn it off if that index only mirrors PyPI. Then a private index in a project file no longer covers the other dependency files. With --check-imports it still stops import lookups. See Private package indexes |
--fail-on high|medium|low |
Lowest severity that fails the run (default low: any issue). All issues are still reported |
--baseline FILE |
Hide the findings recorded in FILE and report only new ones. See Baseline: start with the code you have |
--write-baseline FILE |
Record the current findings in FILE. They are not reported, and later runs with --baseline FILE hide them |
--no-baseline |
Ignore the baseline set in the config and report every finding |
--strict / --no-strict |
Exit 2 if any Python file can't be parsed (by default it's skipped with a warning) |
--jobs N |
Check files in up to N processes. Default: one per CPU, at most 8. --jobs 1 uses a single process. See Speed |
--exit-zero |
Always exit 0 (report only) |
--list-rules |
Show all rules with the severities this project uses |
Exit codes: 0 no issues (or none at or above --fail-on, or none that the baseline doesn't hide), 1 issues found, 2 error (bad options or config, a baseline file that is missing, not valid or can't be written, or unparseable files with --strict), 130 stopped with Ctrl-C.
Run slopfence with a Python at least as new as the syntax your code uses; otherwise newer syntax can't be parsed.
Configuration
Add a [tool.slopfence] table to the pyproject.toml at your project root:
[tool.slopfence]
select = ["SLOP001", "SLOP010", "SLOP020"]  # rules to run (default: all)
ignore = ["SLOP051"]                         # rules to skip
exclude = ["migrations", "tests/fixtures/", "*_pb2.py"]
known-packages = ["corp-auth", "corp-*"]    # private packages that aren't on PyPI
check-imports = false                        # true also looks up imports on PyPI (default: false)
detect-private-index = true                  # false if your private index only mirrors PyPI
fail-on = "high"                             # only high-severity issues fail the run
strict = true                                # unparseable files are an error
jobs = 4                                     # worker processes (default: one per CPU, at most 8)
baseline = ".slopfence-baseline.json"       # hide the findings recorded in this file

[tool.slopfence.per-file-ignores]            # rules to skip in some files
"scripts/*" = ["SLOP040"]
"legacy/" = ["SLOP030", "SLOP011"]

[tool.slopfence.severity]                    # give a rule another severity
SLOP040 = "medium"
exclude works like .gitignore: a pattern without a / in the middle matches any file or folder name anywhere (migrations, *_pb2.py), and a pattern with one is relative to the project root (tests/fixtures/). Excluded files are never checked, but imports of excluded modules still count as your own code. So does a package that an excluded setup.py, setup.cfg or pyproject.toml defines.
per-file-ignores turns rules off in the files that match a pattern. A pattern works exactly like an exclude pattern. Put it in quotes. If several patterns match a file, all their rules are skipped. Unlike exclude, every other rule still checks the file. Two details:
- Dependencies and imports in a file where
SLOP001is off are not looked up on PyPI at all. SLOP030is off for the functions in a matching file. Code anywhere else that copies a helper fromlegacy/is still reported, whichever of the two is older. With--diff, it is only reported when its own lines changed. So a change that only adds a copy of your code insidelegacy/passes a--diffrun, and the next full run reports the older code outside the folder.
severity gives a rule another severity: high, medium or low. Text, JSON and SARIF reports, --fail-on and --list-rules all use it. For example, with SLOP040 = "high" a swallowed exception fails a run that uses --fail-on high.
baseline is explained in Baseline: start with the code you have.
Command-line options (--select, --ignore, --exclude, --known-packages, --check-imports, --detect-private-index, --fail-on, --strict, --jobs, --baseline) replace the matching config values. per-file-ignores and severity can only be set in the config. Unknown keys, rule IDs and severities are reported as errors (exit code 2).
Ignoring a finding
# In a real implementation, use the cache.  # slopfence: ignore[SLOP010]
x = legacy()  # slopfence: ignore
Put # slopfence: ignore-file anywhere in a file to skip it. In a requirements file, pyproject.toml, setup.cfg or Pipfile, add # slopfence: ignore to the end of the line. For an entry that is a table of its own ([packages.name] in a Pipfile, [tool.poetry.dependencies.name]), that is the line of its header. v0.2 reported such a Poetry entry on the line of [tool.poetry.dependencies]. A comment on that line still covers it. In a notebook, add it to the end of the pip install line, or to a comment line right above it. When the command goes on over several lines, the end of its last line counts. Use the line above on Windows, where the shell passes the comment on to pip. # slopfence: ignore-file in any code cell skips the notebook: a Python cell, a %%bash cell or any other.
To skip a rule in whole files or folders, use per-file-ignores. To accept everything a project has today and only see new findings, use a baseline.
Private packages: if your project uses internal packages that aren't on PyPI, list them once in known-packages instead of adding ignore comments everywhere. Names are matched case-insensitively with -, _ and . treated alike (so corp_auth matches corp-auth), and * globs work. Known packages are never looked up on PyPI, and imports of them are never flagged.
SLOP010 (placeholders) also skips test code and demo or example code: files under demo/, examples/ or samples/ folders, or named like demo.py or auth_example.py.
Baseline: start with the code you have
An existing project may have hundreds of findings. A baseline records them once, so slopfence only reports what is new:
slopfence --write-baseline .slopfence-baseline.json   # record today's findings
git add .slopfence-baseline.json
slopfence --baseline .slopfence-baseline.json          # from now on: new findings only
Or set it once in pyproject.toml. Then every run, the pre-commit hook and the GitHub Action use it:
[tool.slopfence]
baseline = ".slopfence-baseline.json"
With a baseline, only new findings are reported, and only new findings fail the run. The summary says how many were hidden:
1 issue (1 medium); 42 more hidden by the baseline
What is recorded. The file has one line per finding:
["src/auth.py", "SLOP011", "validate_token", 1]
That is the file, the rule, what the finding is about, and how many there are. "What it is about" is the package name, the function or test name, or the text of the flagged comment. There is no line number. So a finding stays hidden when you add lines above it, change the code around it, or reformat the file.
When a finding comes back. When you rename the function or the test, reword the comment, or rename or move the file. slopfence then sees a new finding.
Good to know:
- It works with
--diff: only findings on changed lines are reported, and baselined ones stay hidden. It works with--fail-onand with every output format. JSON reports have abaselinedcount. SARIF reports leave baselined findings out. - Two findings in one file that are about the same thing (two
except Exception: passin one function) are counted. If a third appears, one is reported: the one on your changed lines with--diff, otherwise the last one in the file. - Duplicate functions (
SLOP030): a full run reports every copy except the first, so the first copy has no line in the file. It is accepted all the same. With--diff, editing either copy does not bring the pair back, also when the two are only 90% alike afterwards. (If every line of the first copy changes, it can count as a new function.) Near-copies are only looked for with--diff, so a baseline never records one. A near-copy that a change adds is reported. And when you write the baseline again, a pair that is no longer identical drops out of it. A later change to one of the two is then reported, as long as they are still 90% alike. To keep a near-copy, add# slopfence: ignore[SLOP030]to itsdefline. A copy added to a file whereSLOP030is switched off is not reported by a--diffrun: seeper-file-ignores. - When baselined findings are gone, slopfence says so in a note. Run
--write-baselineagain to drop them from the file. The note only comes when the run checks everything the baseline holds. So it never comes with--diff, and not when the paths you give, orexclude,selectandignore, leave out files or rules that the baseline has findings for. It never countsSLOP001: a missing answer from PyPI must not look like a fix. --write-baselinerecords every finding of that run and reports none. Use the options your normal runs use (--select,--check-imports…). Run it online: without answers from PyPI there are noSLOP001findings to record, and a note says so. It can't be combined with--diff.--write-baselineonly replaces a baseline. It stops ifFILEis some other file. It also stops ifFILEholds findings that this run does not check: for files outside the paths you give, for files you exclude, or for rules that are switched off. Check everything the baseline holds, or deleteFILEfirst.baselinein the config is relative to the project root.--baseline FILEis relative to the folder you are in, and it replaces the config value.--no-baselineshows everything again.- The paths inside the file are relative to the project root. That is the git repository the checked path is in. Without git, it is the folder you run slopfence from (or the checked folder, when that is somewhere else), so run slopfence the same way every time. If no file that the baseline names exists there, slopfence says so in a note, and
--write-baselinedoes not replace the file. - A file outside the project (
slopfence . ../shared) is recorded with its full path. That row only matches on a machine where the file has the same path. slopfence only looks at such a file when you give its path to the run. - A baseline file that is missing or can't be read is an error (exit code
2), not an empty baseline. - Files that can't be parsed are not findings, so they can't be baselined. Use
excludefor those.
Where SLOP001 finds dependencies
| File | What is checked |
|---|---|
| Requirements files | Every requirement line. Options, URLs and paths are skipped |
pyproject.toml |
[project] dependencies and optional dependencies, [dependency-groups], Poetry tables |
setup.cfg |
install_requires, setup_requires, tests_require and [options.extras_require] |
setup.py |
The same keywords of setup(), when the list is written in the file, or in a variable that is assigned in the file. The file is read, never run. Anything computed is skipped |
Pipfile |
[packages] and [dev-packages] |
Notebooks (.ipynb) |
pip install lines in code cells: %pip install x, !pip install x, !python -m pip install x, !uv pip install x, and the lines of a %%bash cell. With --check-imports, also the imports in code cells |
A requirements file is a .txt or .in file whose name starts or ends with requirements or constraints: requirements-dev.txt, dev-requirements.txt, requirements.in, constraints.txt. Any .txt or .in file inside a folder named requirements is one too: requirements/base.txt. When the name mentions another package manager (apt-requirements.txt, requirements-conda.txt), the packages in the file are not read: they are not PyPI names. A private index that such a file names still counts. CMakeLists.txt is never read.
A requirements file that is not UTF-8 is not looked up. Windows PowerShell 5 writes UTF-16, for example with pip freeze > requirements.txt. What such a file says about package sources still counts: its index options, and its entries from a URL, a path or git.
Some names are read and never looked up:
- Your own packages. The
namein anypyproject.toml,setup.cfgorsetup.pyof the project is a package of this repository, so a dependency on it is not a hallucination. - Packages from a URL, a path or git.
corp-auth @ git+https://...in one file says wherecorp-authcomes from. It is not looked up there, and not in any other file that names it. Every form ofname @ ...counts (corp-auth @ file:../corp-auth, Hatch'scorp-auth @ {root:uri}/corp-auth), and so does a requirement with a URL anywhere on its line. The same goes for a[tool.uv.sources]entry, a Poetry entry withsource,git,pathorurl, and aPipfileentry withgit,path,file,urlor anindexthat is not PyPI. - Fixture packages. A
setup.py,setup.cfgorPipfileunder a folder namedtestsortestdefines a package that only the tests use. Its dependencies are not looked up and not reported. Its name and its private index still count for the rest of the project. A requirements file or apyproject.tomlunder a test folder is checked like any other. - Lines that are not requirements.
python>=3.9, a file name (vendor.tar.gz), a path, a checksum, and a name with a bracket that is no list of extras (bindep'slibffi-dev [platform:dpkg]). That holds in every file,pyproject.tomltoo. In a requirements file and inpyproject.toml, the two kinds of file that v0.2 read, the name that such a line starts with still counts as declared (corp-authincorp-auth=1.0): with--check-imports, the import of that package is not looked up. A requirements file with more prose than requirements is a document that is only named like a requirements file: none of its names is looked up. So is one with a line that only a document has: an underline (-----,=====,~~~~~), a bullet (- 4 GB RAM,* 4 GB RAM), a directive (.. toctree::), a quote (> note) or a table row (| a | b |). Such a line starts with-,.,=,~,*,+,>,|or a backquote, is no option and no path, and does not go on from a line that ends with a backslash. pip reads no package from such a line. A requirements file with git conflict markers (=======) counts as a document until the conflict is solved. What a document says about package sources still counts: its index options, and its entries from a URL, a path or git.
Lists for another tool. A file with one bare name per line, and no version, extra, marker or option anywhere, may list packages for apt or R. Its names are looked up like any others, because PyPI's answers are what tells such a list from a pip file. If the file's name is not requirements*.txt, and PyPI has fewer of its names than it lacks or gave no answer for, nothing in it is reported.
Known limits: a list for another tool whose names mostly exist on PyPI too (git, docker) is read as a pip file. So is one with a line that pip takes as well: a version in parentheses as Debian writes it (libssl-dev (>= 1.1)), or a constraint such as x1 >= 0. Only PyPI's answers could tell such a file from a pip file. Add such a file to exclude. The same goes for any file you don't want read: exclude = ["setup.py"].
Notebooks. A finding has the line and column of the .ipynb file itself, the lines that git diff shows. So --diff and SARIF work. A notebook saved on one line has all its findings on line 1, at different columns. One limit: when a git clean filter strips the outputs of a notebook on commit (tools like nbstripout can set one up), git diff counts the lines of the stripped text. --diff can then miss a finding in a notebook that still has its outputs in your working copy. Clear the outputs, or run without --diff. Some details:
-
Only
SLOP001reads notebooks, and only their code cells. -
Every notebook of the project is read in every run, also when the run checks other files (one file, as the pre-commit hook does). So a package that a notebook installs from git or a URL is not looked up in the file you check. Only the notebooks you check are looked up themselves.
-
A
pip installcommand is read as text and never run. A command with an option slopfence doesn't know names no package. Neither does apip installin another form than the ones in the table above (pip -q install x,sudo pip install x,/usr/bin/pip install x). An index or links option in such a command still counts, whatever its value is. When a command holds a variable ($PKG,{pkg},%PKG%), none of its names is looked up. -
With
--check-imports, the imports of a notebook are only looked up when the notebook installs everything it uses by name. A module that a cell writes (%%writefile utils.py) is the notebook's own. The imports are not looked up at all when any import may come from a place slopfence can't see:- One of its
pip installlines installs something without a name: a path, a URL without#egg=,-r requirements.txt,-e ., a variable, a command with an option slopfence doesn't know, or apip installin a form it doesn't read (sudo pip install x). - It installs with another tool:
conda installormamba install(also%conda install),uv add,poetry add,pipenv install, orpython setup.py install/develop. slopfence reads no package name from such a line. - It brings in code at run time with a shell command:
git clone,wget,curl,gdown,unzip,tar,7z,cp -r, orcp,mvorlnwith a.pyfile. - It changes where Python looks for modules: a
%cdline (also without the%),os.chdir, or the textsys.pathorPYTHONPATHin a code cell.
Known limits: code that reaches the notebook without a trace in it (a Kaggle utility script, a file uploaded by hand) is not seen. Neither is one of these commands in another form: behind
sudo, with an option before the subcommand (git -C dir clone), run from Python (os.system,subprocess), or a tool that is not in the list (micromamba,python -m spacy download). The import is then reported when PyPI has no package of that name. Add the name toknown-packages. - One of its
-
The imports of a code cell with a carriage return inside a line (not at its end) are not looked up: Python counts the lines of such a cell in another way than the file does.
-
A notebook larger than 20 MB is not read, and a note says so.
-
To leave notebooks out, add
"*.ipynb"toexclude. An excluded notebook is not read at all.
What slopfence sends over the network
slopfence only talks to one server, https://pypi.org, and only for SLOP001. It sends a request per package name (HEAD https://pypi.org/pypi/<name>/json) and nothing else: no code, no file names, no telemetry. Up to 8 requests are sent at a time. That changes how fast the answers arrive, not what is sent.
| Names sent to PyPI | When |
|---|---|
Dependencies declared in requirements files, pyproject.toml, setup.cfg, setup.py, Pipfile, and pip install lines in notebooks (see Where SLOP001 finds dependencies) |
By default. These names are already meant for a package index. Entries installed from URLs, paths or git are never sent, also where another file names the same package without the URL. Neither is a package of your own project, a dependency of a fixture package under a test folder, or any dependency that may come from a private index (see Private package indexes) |
| Imports in your source code and notebooks that aren't in the standard library of any Python 3, installed, part of your project, or provided by a declared or locked package | Only with --check-imports (or check-imports = true). This can catch an invented package that was imported but never declared, but for private code it may reveal internal package names |
Names in known-packages are never sent. Neither are the dependencies and imports of a file where SLOP001 is switched off with per-file-ignores, or a dependency or import under an ignore comment (# slopfence: ignore on its line, or # slopfence: ignore-file). Answers are cached for a day (missing) or a week (found) in ~/.cache/slopfence, so repeated runs send fewer requests. With --diff, only the dependency files in the diff are looked up. --offline sends nothing at all.
Private package indexes
If your packages may come from an index other than PyPI, a name that PyPI doesn't know could be a private package. slopfence then doesn't report it and doesn't send it to PyPI. It looks for private indexes in:
| Where | What counts as private |
|---|---|
| Requirements files | -i / --index-url / --extra-index-url with a non-PyPI URL, -f / --find-links, --no-index, on a line of options or after a requirement: that file's packages |
pyproject.toml |
[[tool.poetry.source]] (except explicit ones), [[tool.uv.index]] (except explicit ones), [tool.uv] index-url / extra-index-url (also under [tool.uv.pip]), [[tool.pdm.source]]: that file's packages. A per-dependency Poetry source or [tool.uv.sources] entry: that package |
Pipfile, Pipfile.lock |
A [[source]] that isn't PyPI: that Pipfile's packages. An entry with git, path, file, url, or an index that is not a PyPI source: that package |
setup.cfg, setup.py |
dependency_links, and in setup.cfg also [easy_install] with find_links or with an index_url that is not PyPI: that file's packages, and those of the setup.py or setup.cfg in the same folder (setuptools reads the two as one) |
| Notebooks | An index option in a pip install line (-i, --index-url, --extra-index-url, uv's --index) with a non-PyPI URL: that notebook's packages. Any code cell that mentions an index setting anywhere else (pip config, PIP_INDEX_URL, PIP_CONFIG_FILE, UV_INDEX, pip.conf, codeartifact, keyring): the same. That includes a pip install line that names such a thing as a package or as another option (pip install keyring, --keyring-provider). -f / --find-links or --no-index in a pip install line: that notebook's packages and imports, and nothing else |
| Environment variables | PIP_INDEX_URL, PIP_EXTRA_INDEX_URL, UV_INDEX, UV_DEFAULT_INDEX, UV_INDEX_URL, UV_EXTRA_INDEX_URL |
| pip configuration | pip.conf / pip.ini in pip's global, user and virtualenv locations, and PIP_CONFIG_FILE ([global] and [install] sections) |
| uv configuration | uv.toml in the project, user and system config folders, or UV_CONFIG_FILE (UV_NO_CONFIG turns this off), including its [pip] table used by uv pip install |
A private index in a project file stops lookups for that file's dependencies, and for imports with --check-imports.
It also stops lookups for the dependency files that v0.2 did not read: setup.py, setup.cfg, Pipfile, notebooks, and requirements files with any name but requirements*.txt. These files rarely name an index themselves, and they are often installed together with a file that does (pip install -r requirements.txt -c constraints.txt). So when a requirements file, pyproject.toml, Pipfile or Pipfile.lock anywhere in the project uses a private index, their dependencies are not looked up, and the report says so in a note. A pyproject.toml, Pipfile or Pipfile.lock that can't be read counts in the same way. It may be broken, written in a newer TOML than Python reads, or not UTF-8, and it may set an index that slopfence can't see. The note then names that file. "Anywhere" leaves out the folders slopfence never reads: a checkout nested inside the project (a git worktree, clone or submodule), .git, virtual environments (.venv, venv, env), node_modules, site-packages, build, dist, .tox, .nox, .eggs, *.egg-info and cache folders. A file or folder that you name on the command line in one of these folders, or outside the project, is still checked (slopfence . vendor/lib/setup.py). It is checked together with the dependency and lock files of its own checkout: the nearest folder above it that holds a .git. A private index there then counts for the run. Without a checkout, a named file is checked together with the files that lie directly in its own folder, and a named folder with what it holds itself. The folders above are not read. You can change what counts in two ways:
- An index in an excluded file doesn't count.
detect-private-index = falseswitches this off. The dependencies of the other files are then looked up again. With--check-imports, a private index in a project file still stops import lookups.
--find-links and --no-index name no index. They only ever cover their own file.
A private index in your environment (variables, pip or uv configuration) could serve any package, so SLOP001 makes no lookups at all and the report says so in a note. An index is public only if its host is pypi.org, files.pythonhosted.org or pypi.python.org. TestPyPI (test.pypi.org) is another index, so it counts as private. slopfence never prints index URLs, because they can contain credentials.
If your company index only mirrors PyPI, set detect-private-index = false (or pass --no-detect-private-index) to check packages against PyPI again, and list your own private packages in known-packages.
Imports with a different package name
With --check-imports, an import isn't looked up when a declared dependency or a locked package provides it, even if the names differ and the package isn't installed where slopfence runs. For example, import bs4 is covered by beautifulsoup4, import dateutil by python-dateutil, and from google.cloud import storage by google-cloud-storage. slopfence reads uv.lock, poetry.lock, pdm.lock and Pipfile.lock, so indirect dependencies count too (import idna when only requests is declared).
A module of Python's standard library is never looked up, also one that the Python slopfence runs on does not have. imp, asyncore and cgi were removed in Python 3.12 and 3.13, and tomllib came with Python 3.11. So the same file gets the same report on every Python.
What the code-quality rules skip
To keep false positives low, the newer rules are deliberately conservative:
SLOP011stub functions needs a docstring that promises work (it starts with a verb like validate, fetch, send, calculate) or admits it isn't done (placeholder, TODO, for now). The body must then return hardcoded data while ignoring every input, or return nothing although the return type promises a value. A placeholder docstring over a body that does nothing (pass,...,return None) is reported even without a return type..pyistub files are never checked. Abstract methods,@overload, properties,Protocol/ABC classes,if TYPE_CHECKING:blocks, documented hooks ("override this", "does nothing by default") and tests are skipped.SLOP030duplicate functions ignores functions with fewer than 3 statements and test code. Parameter and variable names and docstrings don't matter; called functions, attributes and constants do. A full scan reports identical copies (every copy except the first). "The first" is the first by path, and files whereSLOP030is switched off withper-file-ignoresalways count as first. With--diff, functions you changed are also compared with the rest of the project and reported when they're ≥90% similar to an existing function, because that's when an assistant re-writes a helper that already exists. Never reported: methods with the same name in different classes (plugins, drivers), functions defined twice in one file (underif/try), near-duplicate methods, and parallel families that differ only by swapped names, operators or constants (md5_utf8/sha_utf8,polyadd/polysub).SLOP040swallowed exceptions only flagsexcept Exception,except BaseExceptionand bareexcept:whose body is justpassor.... A comment in the handler (# best effort), cleanup code (__del__,__exit__,close(),atexithandlers,try: os.unlink(...), also in a loop), optional imports (try: import ujson),contextlib.suppress, tests and examples are skipped.
Speed
slopfence reads and checks files in several processes at once. The report is the same with any number of them.
- By default it uses one process per CPU, at most 8. Change it with
--jobs Norjobs = N.--jobs 1uses a single process. - Small projects don't need it. Worker processes only start when there are 200 or more Python files to read, one for every 100 files.
- Each worker needs 40 to 80 MB of memory on a big project. In a container with little memory, set
jobs = 1or2. - If worker processes can't start, or one dies, slopfence prints a warning and checks the files in one process.
- Worker processes need a Python that can keep a new process from importing files of the project it checks: Python 3.11 or newer (not started with
-E), or any Python started with-I. Python 3.10 has no such switch, so there workers are only used where they are forked (Linux). Otherwise slopfence prints a warning and uses one process. - If slopfence is stopped or killed, its worker processes end too.
- PyPI lookups are sent 8 at a time.
Example: the CPython standard library and 127 installed packages (22,864 files) take 35 to 45 seconds with 8 jobs on a laptop with 4 cores, and a little over 2 minutes with one process. v0.2 needed almost 6 minutes and 8 GB of memory for the same files. Now the main process needs about 0.3 GB.
GitHub Action
# .github/workflows/slopfence.yml
name: slopfence
on: pull_request
permissions:
  contents: read
jobs:
  slopfence:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v5
        with:
          fetch-depth: 0
      - uses: syedmuhdahmad/slopfence@v0.2.0
On pull requests it automatically checks only the changed lines (set diff: none to check everything, or diff: <ref> for a specific ref). To show findings inline on the pull request, set sarif-file: slopfence.sarif and upload it with github/codeql-action/upload-sarif (needs security-events: write).
A baseline in your pyproject.toml applies here too: baselined findings are not reported, and they are left out of the SARIF file.
pre-commit
# .pre-commit-config.yaml
repos:
  - repo: https://github.com/syedmuhdahmad/slopfence
    rev: v0.2.0
    hooks:
      - id: slopfence
The hook reads the same [tool.slopfence] config, so per-file-ignores, severity and baseline apply to it too.
The problem
AI coding tools (Claude, Copilot, Cursor, Gemini, Codex and others) are now part of everyday development. They write code fast, and that code usually looks correct. It compiles, it's well formatted, and it has comments and tests.
But it often comes with recognizable junk:
- Packages that don't exist. The AI imports
flask-jwt-simple-authbecause the name sounds plausible. Attackers now register these invented names to spread malware, a technique known as slopsquatting. - Tests that test nothing. A test creates a mock, sets a value on it, then asserts that value. It passes forever and protects nothing.
- Placeholder code shipped as real code. Comments like
# In a real implementation, validate the tokenabove a function that returnsTrue. - Duplicate helpers.
format_date(),formatDate()anddate_formatter()in three different files, because the AI wrote a new helper instead of finding the existing one. - Over-defensive code.
try/except Exception: passaround code that can't fail, which hides real errors. - Comment noise.
# Increment counter by 1abovecounter += 1, or leftover chat text like "Here's the updated function:".
Reviewers miss these because the code looks fine. Each one is small. Together they add up to security holes, false confidence from green test suites, and codebases that get harder to maintain every sprint.
Why existing tools aren't enough
| Tool | What it's good at | What it misses |
|---|---|---|
| Ruff, ESLint, Pylint | Style and common bugs | AI-specific patterns, invented packages |
| Vulture, Knip | Dead code | Fake tests, placeholders, near-duplicates |
| jscpd | Copy-pasted code | Code that's similar but not identical |
| Socket, Snyk | Supply-chain security | Code-quality patterns; mostly paid |
| slopcheck (unrelated project) | Checking for hallucinated packages before you install them | Code-quality patterns such as fake tests, placeholders and chat leftovers |
AI code reviewers (e.g. Claude /code-review) |
Deep, context-aware review | Not deterministic, costs tokens, doesn't automatically check package registries, runs only when someone asks |
No single tool focuses on the failure modes of AI-written code, built for reviewing pull requests. That's the gap slopfence fills.
slopfence vs. AI reviewers: complementary, not competing
Developer + AI writes code
        │
        ▼
slopfence            ← fast, free, same result every time; runs on every commit
        │
        ▼
AI / LLM review      ← deep reasoning about logic and design
        │
        ▼
Human review
AI reviewers are smart but nondeterministic and cost money on every run. slopfence catches the objective, repeatable problems in seconds with no API keys, so reviewers (human or AI) can spend their attention on what matters.
Who needs it
- Teams adopting AI coding tools that want a safety net without banning the tools.
- Open-source maintainers reviewing a growing number of AI-generated pull requests.
- Security teams worried about hallucinated or slopsquatted dependencies.
- Tech leads who want an objective quality gate instead of arguing over style in review.
- Solo developers who want to catch their AI assistant's mistakes before they commit.
Design principles
- Detect patterns, not authorship. slopfence never tries to guess whether AI wrote the code. That's unreliable and leads to arguments. It flags low-quality patterns that AI commonly produces, no matter who wrote them.
- Deterministic by default. Rule-based checks with no LLM required. The same input always gives the same output.
- Diff-first. Check only what changed in a pull request. Nobody wants 4,000 warnings on an old codebase.
- Low false positives over high recall. A noisy linter gets uninstalled. Start strict, flag only obvious cases, and make everything configurable.
- Fits existing workflows. CLI, pre-commit hook, GitHub Action, and SARIF output for GitHub code scanning.
Detectors
| ID | Detector | Severity | Status |
|---|---|---|---|
SLOP001 |
Dependency (or, with --check-imports, import) of a package that doesn't exist on PyPI |
🔴 High | ✅ v0.1 (Python) |
SLOP002 |
Dependency that is very new or has suspiciously few downloads (slopsquatting risk) | 🔴 High | Planned |
SLOP010 |
Placeholder / stub comment (In a real implementation…, Simplified for demo) |
🟠 Medium | ✅ v0.1 |
SLOP011 |
Function whose docstring promises work ("Validate the token") but which only returns hardcoded data or nothing | 🟠 Medium | ✅ v0.2 |
SLOP020 |
Test that only asserts on its own mocks | 🔴 High | ✅ v0.1 |
SLOP021 |
Test with no meaningful assertion (e.g. only assert True) |
🟠 Medium | ✅ v0.1 |
SLOP022 |
Test wrapped in try/except so it can never fail |
🔴 High | ✅ v0.1 |
SLOP030 |
Function identical to another one in the project (names and docstrings ignored); with --diff, also new functions ≥90% similar to existing ones |
🟠 Medium | ✅ v0.2 |
SLOP040 |
except Exception (or bare except) that silently swallows every error |
🟡 Low | ✅ v0.2 |
SLOP050 |
Comment that only restates the code | 🟡 Low | Planned (#23) |
SLOP051 |
Leftover chat text in code (Certainly! Here's…) |
🟠 Medium | ✅ v0.1 |
Example output
$ slopfence --diff main
requirements.txt
  2:1      SLOP001  Dependency 'flask-jwt-simple-auth' does not exist on PyPI (possible hallucination)  [high]

src/auth.py
  5:5      SLOP010  Placeholder left in code: "In a real implementation, validate the token signature."  [medium]

tests/test_billing.py
  7:5      SLOP022  Test 'test_refund' catches assertion failures without re-raising, so it can never fail  [high]

tests/test_user.py
  4:1      SLOP020  Test 'test_user_name' only asserts on its own mocks and never calls real code  [high]

4 issues (3 high, 1 medium)
Architecture
┌─────────────┐   ┌──────────────┐   ┌──────────────┐   ┌───────────────┐
│   Files /   │──▶│    Parser    │──▶│  Rule engine │──▶│   Reporter    │
│   git diff  │   │ (ast / t-s)  │   │  (detectors) │   │ CLI/JSON/SARIF│
└─────────────┘   └──────────────┘   └──────┬───────┘   └───────────────┘
                                            │
                                  ┌─────────▼─────────┐
                                  │ Optional:         │
                                  │ - registry lookup │
                                  │   (cached)        │
                                  │ - LLM second      │
                                  │   opinion (--llm) │
                                  └───────────────────┘
- Parser: slopfence uses Python's built-in
astandtokenize(no dependencies). tree-sitter is planned so new languages can be added without rewriting the detectors. - Workers: files are parsed and checked in worker processes when there are enough of them (see Speed). Only a small summary of each file comes back: its findings, function fingerprints and import names. So memory stays low. Registry lookups stay in the main process.
- Registry lookups are cached locally (
~/.cache/slopfence) to stay fast and avoid rate limits. If PyPI can't be reached, nothing is flagged: an unknown answer is never treated as "missing". Import names are only sent with--check-imports(see What slopfence sends over the network). - Optional LLM mode (planned, not built yet) would send only the unclear cases for a second opinion. Never required.
Challenges (and how we plan to handle them)
| Challenge | Why it's hard | Plan |
|---|---|---|
| False positives | Every noisy warning erodes trust; one bad week and teams disable the tool. | Conservative rules, severity levels, # slopfence: ignore[SLOP0xx] comments, per-file ignores, a baseline for the findings a project already has, and a test corpus of real-world false positives. |
| Private / internal packages | Internal packages look identical to hallucinated ones. | Allowlists, private registry support, and reading local lockfiles and workspace packages. |
| Registry rate limits | Checking every import against PyPI/npm on every run is slow and gets throttled. | Local cache with TTL, batch lookups, offline mode. |
| "Is this really junk?" | Some patterns (defensive code, stubs) are legitimate in context. | Flag only high-confidence cases by default; stricter checks are opt-in. |
| Near-duplicate detection at scale | Comparing every function with every other is expensive. | AST normalization + hashing, and only comparing changed functions against the index. |
| Multi-language support | Each language has different idioms and test frameworks. | Start with Python only, do it well, then JS/TS via tree-sitter. |
| Tone and adoption | A tool that "shames AI users" will be resisted. | Position it as a quality gate for AI-assisted development, not against it. |
| Moving target | AI tools improve and their failure modes change. | Rules are data-driven and easy to add; community-contributed detectors. |
Roadmap
v0.1 (MVP): Python
- CLI:
slopfence .andslopfence --diff <branch> -
SLOP001packages that don't exist on PyPI (dependency files and imports) -
SLOP010placeholder comments -
SLOP020/SLOP021/SLOP022fake tests -
SLOP051leftover chat text - Ignore comments
- JSON and SARIF output
- GitHub Action and pre-commit hook
- Publish to PyPI
v0.2: private code, new rules (released)
Tracked in the v0.2.0 milestone. Upcoming work is on the roadmap board.
Planned features
Reliability
- Test the GitHub Action in a real workflow, including SARIF upload (#13)
- Test the pre-commit hook with
pre-commit(#14) - Allowlist for private packages (#15)
- Better import-name to package-name mapping (#16)
- Detect private indexes from
pip.conf, uv and Poetry (#17) -
--fail-onseverity threshold (#18) - Option to fail on unparseable files (#19)
- Fewer
SLOP010false positives from "for demo purposes" (#20) - Import lookups are opt-in, so private package names aren't sent to PyPI (#34)
- Smaller source distribution (#35)
New rules
-
SLOP040except Exceptionthat silently swallows errors (#21) -
SLOP011stub functions that onlypassor return fake data (#22)
Project
Later
-
SLOP050comments that only restate the code (#23) - Parallel processing for large repos (#12)
- Baseline mode: fail only on new findings (#51)
- Per-file ignores and per-rule severity overrides (#52)
-
SLOP001also checkssetup.py,setup.cfg,Pipfile, notebooks and more requirements file names (#53) - JavaScript / TypeScript (npm registry)
- Slopsquatting risk scoring (
SLOP002) - VS Code extension
- Optional
--llmsecond opinion
Contributing
The project is at the very start, which is the best time to shape it.
- 💡 Have an example of AI-generated junk? Open an issue with a code snippet. Real examples are the most valuable input for designing detectors.
- 🐛 Know a pattern we're missing? Propose a detector in an issue.
- 🗣️ Disagree with the approach? Open a discussion. Better now than after v1.
Please read CONTRIBUTING.md before opening a pull request. Everyone taking part is expected to follow our Code of Conduct. Found a security issue? Report it privately as described in SECURITY.md. Need help? See SUPPORT.md.
License
来源:GitHub · github.com