RuneForgeAI 的 Project A.E.S.I.R.:Mojo 原生本地推理引擎进展
hrabanazviking/RuneForgeAI-Project-Aesir
RuneForgeAI 的 Project A.E.S.I.R. 是一个用 Mojo 编写的实验性原生本地推理引擎,已从原型进入可实际运行模型的阶段,支持 GGUF 模型文件及原生 CPU 与 NVIDIA CUDA 推理路径,并已跑通 Gemma、Llama 3/Stheno 和 Qwen 系列测试模型。
2026-10-01: speed roadmap. The AESIR speed-lead roadmap targets a measured 2× lead over current Ollama in each designated meaningful workload, with a 3× stretch goal. It starts from the actual installed-provider comparison: cached 32-token work is near parity, while new long input and 128-token output still trail Ollama. The roadmap defines future measurement, matrix-prefill, decode, memory and stability work; its targets are not achieved results.
2026-10-01: native CUDA efficiency. The exercised Llama 3.2 3B/RTX 2060 subset is another 1.60–1.66x faster than the preceding release, with matching complete replies and unchanged GPU allocation. Operation and verification. Bifröst keeps its existing Ollama provider policy; native/Ollama templates and cache policies differ. Second-brain setup.
Project A.E.S.I.R. is an experimental native-Mojo engine for running local AI models directly on your own hardware, and it is evolving from a working low-level inference engine into a practical backend that ordinary AI applications can eventually use.
| Project Aesir in Plain English | Project Status Report Aug-30-2026 | Engineering Doctrine | Agent Onboarding | Architecture | Capability Ledger | Cognitive Inference Architecture | Bare Metal Programing | Mojo Programming Guide | Mojo Programming Language Guide | Mojo Programming Language Reference | Debugging Playbook | Error Taxonomy | GIT Discipline | Glossary | Mythic Engineering for Project Aesir | Project Aesir Core Spec 1 | Roadmap Reality First Completion | Security Posture | Doom Loop Annihilation Protocol | Testing Protocol | Neural Spectral Fractal Inference | GPU / NPU Real Excution Gameplan | Heterogeneous Compute | Bare Metal Compute Field Manual | How to Use Aesir as of Sept-16-2026 | Project Aesir What Works as of Sept-16-2026 |
Project A.E.S.I.R. in Plain English
Easy introduction for non-technical readers
Snapshot date: September 16, 2026
This document describes Project A.E.S.I.R. as it exists on the date above. A.E.S.I.R. is developing quickly, so newer repository documentation may supersede details here.
What is Project A.E.S.I.R.?
Project A.E.S.I.R. (Advanced Edge System for Interface and Response) is an experimental program for running AI models locally on your own computer.
The easiest way to understand it is to compare it with familiar local-AI software such as Ollama. An application asks for an AI response, the local inference engine loads the AI model and performs the enormous amount of math needed to produce the answer. A.E.S.I.R. is being built to become that underlying engine.
The unusual part is how A.E.S.I.R. is being built. Its inference runtime is written in Mojo and is intended to work close to the hardware instead of depending on a large Python AI software stack. The long-term goal is an efficient, hardware-aware engine that can eventually make good use of many kinds of computers and accelerators, especially consumer and edge hardware.
A.E.S.I.R. is not finished software for ordinary end users yet. It is an active experimental engineering project. However, it has already crossed the important line from design documents and prototypes into running real AI models through its own native inference paths.
What does "local AI" mean?
Many AI services send your request over the Internet to computers in a data center. Local AI instead runs the model on hardware you control.
In the parts of A.E.S.I.R. that are currently verified, the model is loaded from local storage and inference happens locally. That can eventually provide benefits such as offline use, privacy, independence from a hosted inference service, and the ability to choose your own models.
A.E.S.I.R. does not currently claim to support every computer, every model, or every AI application.
What is an AI model in this project?
Think of an AI model as a very large collection of learned numerical information plus an architecture that describes how to use it.
A.E.S.I.R. works with GGUF model files in its currently verified model paths. GGUF is a popular file format for distributing models intended for local inference.
A.E.S.I.R. can inspect GGUF information, store model files in its own local model catalog, verify their contents, and run specific supported model families through native CPU or NVIDIA CUDA paths.
What is actually working right now?
As of September 16, 2026, the repository contains real working implementations for a growing set of capabilities.
Real native inference
A.E.S.I.R. has a verified native Mojo CPU reference path using a pinned Llama GGUF fixture. It also has native NVIDIA CUDA inference paths that have physically run real Gemma, Llama 3/Stheno, and more recently Qwen-family test models on the project's exercised NVIDIA hardware.
The CUDA paths keep the important inference work on the GPU rather than calling Ollama, llama.cpp, a hosted AI API, or a Python inference framework to secretly generate the answer.
Interactive local chat
A.E.S.I.R. can keep a supported CUDA model loaded and hold an interactive chat session. It supports sampling controls such as temperature, top-k, top-p, min-p, seeds, and repetition controls on the verified CUDA chat paths.
It also supports conversation save/load behavior, model selection, aliases, favorites, and model switching in the newer CLI work.
Saved exact-token snapshots can be organized without renaming arbitrary files:
python3 scripts/conversations.py save "My saga" --snapshot .aesir/saga.aesir
python3 scripts/conversations.py list
python3 scripts/conversations.py open "My saga" --expect-model sha256:YOUR_MODEL_DIGEST
python3 scripts/conversations.py rename "My saga" "My saga — chapter one"
python3 scripts/conversations.py export "My saga — chapter one" --output .aesir/saga.md
open prints the validated native snapshot path for /load. The library never
overwrites a name or export. Native chat can separately opt into crash-recovery
autosave generations:
mkdir -p -m 700 "$HOME/.local/state/aesir/sessions/saga"
aesir chat MODEL --accel cuda \
  --autosave-dir "$HOME/.local/state/aesir/sessions/saga" --autosave-retain 3
The directory must already exist, belong to the current user, and have no
group/world permissions. A restart with the same compatible model and options
restores the latest committed generation and reports any interrupted turn.
Healthy pre-generation failures keep the session usable and discard only
uncommitted autosave intent. Interrupted prefill explicitly requires /clear.
Invalid model switches fail before unload; a target startup failure after unload
names the previous model to restart instead of pretending rollback succeeded.
The local model catalog also supports one-way legacy migration and explicit, non-overwriting backups with validate-before-replace restore:
aesir catalog migrate ./legacy.catalog --model-store .aesir/models
aesir catalog backup ./catalog.backup --model-store .aesir/models
aesir catalog restore ./catalog.backup --model-store .aesir/models
A friendlier terminal Home screen
The built application now has a terminal-oriented Home interface:
aesir home --model-store .aesir/models
It provides an easier entry point for chat, model catalog browsing, diagnostics, and repair preview instead of requiring users to remember every command.
Local model catalog
A.E.S.I.R. has a native content-addressed model store. In plain language, this means it can keep a local catalog of installed models and identify stored model bytes by a cryptographic SHA-256 fingerprint.
The model-store tools can currently create/import entries, list models, show information, verify stored bytes, copy catalog entries, remove entries, garbage-collect unreferenced model data, create aliases, and mark favorites.
Model downloading
A.E.S.I.R. has native tooling for pinned Hugging Face GGUF downloads. The download path validates expected file size and SHA-256 information before treating a pinned artifact as verified. Default single-connection pulls continue a safe deterministic partial and bind transfer, validation, sync, and publication to one opened inode.
Hardware and memory planning
A.E.S.I.R. can report hardware information and estimate whether a model fits available memory. New September 16 work added more explicit explanations of memory-fit decisions, including required, available, reserved, usable, deficit, and headroom byte counts.
This is important because "will this model fit on my GPU?" is one of the most common practical problems in local AI.
Model inspection
The CLI can inspect GGUF model information without pretending that inspection proves the model can execute successfully:
aesir inspect <model> --format json
The September 16 implementation also versions the native layout evidence it reports.
Diagnostics
The aesir doctor command checks useful local conditions such as CUDA, model storage integrity, disk visibility, local listeners, and model compatibility. It is designed to remain useful offline.
Local AI server
A.E.S.I.R. can run a local HTTP inference service backed by a loaded native CUDA model.
It has its own authenticated local API and an initial Ollama-compatible mode. The Ollama-compatible mode currently implements model/version discovery plus non-streaming text generation and chat for the supported service path.
It also has OpenAI-compatible text API work in the current runtime.
This is a major architectural step because other programs can eventually use A.E.S.I.R. as their AI engine instead of needing to know how A.E.S.I.R. performs inference internally.
What does "Ollama compatible" mean here?
It does not yet mean "A.E.S.I.R. can replace every Ollama feature."
It means A.E.S.I.R. already understands part of the same local HTTP language used by Ollama clients. The currently documented Ollama-compatible service includes:
- version information
- installed-model discovery
- model information
- text generation
- chat
- common generation settings
Important pieces are still being developed, including streaming responses, embeddings, additional model-management endpoints, tool calling, multimodal messages, and broader concurrency/lifecycle behavior.
Full application compatibility is therefore a development target, not a current blanket claim.
Why Mojo?
Mojo is a systems-oriented programming language designed for high-performance computing and AI workloads.
A.E.S.I.R.'s native inference runtime uses Mojo so that the project can work much closer to CPUs and accelerators while retaining a higher-level programming model than writing the entire engine in low-level GPU assembly or C/C++.
The long-term hope is that this helps A.E.S.I.R. become portable across increasingly diverse hardware without turning the project into a pile of unrelated inference engines.
What is CUDA?
CUDA is NVIDIA's GPU computing platform. A GPU contains a huge number of small computing resources that are well suited to the matrix and vector calculations used by AI models.
A.E.S.I.R.'s most capable physically verified inference paths today use NVIDIA CUDA. That does not mean the project intends to remain NVIDIA-only. AMD, Intel, Apple, NPUs, heterogeneous execution, and multi-device work are longer-term goals, but they should not be confused with currently verified support.
What is quantization?
AI models can be extremely large. Quantization stores model numbers using fewer bits so models consume less memory and can often run faster.
A.E.S.I.R. contains substantial work around GGML/GGUF quantization formats, including checked K-quant decoding and experimental/host primitives for several additional quantization families.
Some quantization code is verified as a mathematical primitive without yet being connected to complete model execution. The repository's Capability Ledger is the authority for that distinction.
What is the KV cache?
While an AI writes a response, it needs to remember mathematical information from earlier tokens. That working memory is commonly called the KV cache.
The currently used CPU/CUDA model sessions use preallocated contiguous KV storage. A.E.S.I.R. also has a separate checked host paged-KV pool that can manage pages for multiple logical sequences, but that paged system is not yet the live attention cache for normal model execution.
That distinction matters: having a component implemented is not the same thing as claiming the entire future architecture is already connected.
What makes A.E.S.I.R. different from a simple AI demo?
A.E.S.I.R. is being developed as an inference runtime and local-AI backend, not merely a script that loads one model and prints text.
Around inference itself, the project is developing:
- model storage and verification
- hardware discovery
- memory planning
- model-family detection
- tokenization
- quantization support
- GPU kernels
- persistent chat sessions
- sampling
- configuration and model recipes
- diagnostics
- local HTTP serving
- Ollama-compatible APIs
- OpenAI-compatible APIs
- safe local launch tooling
- Windows-to-WSL launch support
- testing and evidence tracking
The goal is for these pieces to form reusable infrastructure for applications rather than remaining disconnected experiments.
Can I use it instead of Ollama today?
For experiments with A.E.S.I.R.'s currently supported service surface, yes. As a complete general-purpose Ollama replacement, no, not yet.
The current Ollama-compatible server is useful enough to test real clients that only need its implemented endpoints and non-streaming generation. It is not yet a complete replacement for all Ollama features or all applications built around Ollama.
A major future compatibility goal is to make polished applications able to use A.E.S.I.R. without needing application-specific inference code.
Can I run it on Windows?
The current practical Windows path is Windows 11 + WSL2. A PowerShell launcher is included to enter the prepared WSL environment and launch the verified local A.E.S.I.R. build.
This is not the same as a native Windows Mojo binary. The current documented inference environment remains Linux/WSL-oriented.
Can I run it on AMD, Intel, Apple Silicon, a phone, or an NPU?
Those directions are part of the broader project vision, but the answer for ordinary supported use today is not yet.
The strongest current accelerator evidence is the NVIDIA CUDA path. The project deliberately separates future architecture from verified present capability.
Is A.E.S.I.R. production ready?
No. It is experimental software under rapid development.
The local server is deliberately loopback-only and is not presented as an Internet-facing, multi-user production service. Model-family coverage, hardware coverage, performance benchmarking, concurrency, embeddings, multimodal support, and other areas are still growing.
Where should technical readers go next?
Start with these repository documents:
README.mdfor the main project overview.CAPABILITY_LEDGER.mdfor the authoritative evidence-backed capability status.docs/NATIVE_RUNTIME.mdfor native inference details.docs/NATIVE_SERVICE.mdfor the local HTTP/Ollama-compatible service.docs/MODEL_STORE.mdfor local model management.docs/LOCAL_LAUNCH.mdfor Linux/WSL/Windows launch behavior.BEST_IN_CLASS_GAMEPLAN.mdfor the active ordered implementation campaign.
For a dated practical snapshot written for ordinary users, see HOW_TO_USE_PROJECT_AESIR_RIGHT_NOW_2026-09-16.md and PROJECT_AESIR_WHAT_WORKS_NOW_2026-09-16.md in this directory.
The one-sentence version
Project A.E.S.I.R. is an experimental native-Mojo engine for running local AI models directly on your own hardware, and it is evolving from a working low-level inference engine into a practical backend that ordinary AI applications can eventually use.
How to Use Project A.E.S.I.R. Right Now
Easy practical guide
Current as of September 16, 2026
Why this guide has a date: A.E.S.I.R. is changing rapidly. Commands, supported models, setup requirements, and compatibility features are likely to change. Treat this as a September 16, 2026 snapshot and check newer repository documentation when available.
Who is this guide for?
This guide is for someone who understands basic computer tasks and can paste commands into a terminal, but does not necessarily understand AI inference engineering, CUDA kernels, GGUF internals, Mojo, or model architecture.
A.E.S.I.R. is still experimental developer software. It is becoming easier to use, but this is not yet a one-click consumer application.
1. What can I realistically do with A.E.S.I.R. today?
On a currently supported setup you can:
- build the native A.E.S.I.R. program
- launch its terminal Home screen
- inspect your local model catalog
- import GGUF model files into A.E.S.I.R.'s protected model store
- verify stored model files
- give models shorter aliases and favorites
- inspect GGUF information
- inspect hardware and memory-fit information
- run diagnostics with
aesir doctor - chat interactively with supported native CUDA models
- run a local authenticated A.E.S.I.R. HTTP service
- run the early Ollama-compatible local service
- experiment with applications that only require the currently implemented Ollama/OpenAI-compatible text surface
You should not expect arbitrary GGUF files, every GPU vendor, every Ollama client feature, embeddings, vision, tools, or Internet-facing serving to work yet.
2. The easiest currently documented environment
The current practical environment is:
Linux x86-64
or
Windows 11 → WSL2 → Linux A.E.S.I.R.

plus

NVIDIA GPU + working NVIDIA/WSL CUDA support
The repository's exercised CUDA development target is NVIDIA Ada sm_89. Compilation for another target does not by itself prove that target physically works.
You also need the repository's already prepared/installed development environment, including Python 3, Pixi, the locked Mojo environment, required system libraries, and an NVIDIA driver appropriate to your setup.
A.E.S.I.R.'s inference runtime itself is native Mojo. Python in the launch workflow is launch/build plumbing, not the code secretly performing model inference.
3. Start from the repository checkout
Open a terminal in your local A.E.S.I.R. repository checkout.
For Windows, use the WSL distribution in which you prepared the A.E.S.I.R. environment. Keep the checkout and prepared environment on local storage appropriate to the documented setup.
4. Build a fresh local executable
On Linux or inside WSL:
python3 scripts/launch.py --build
Then verify that the prepared build still matches the checkout:
python3 scripts/launch.py --check
A normal launch deliberately does not rebuild or download dependencies behind your back. If source files changed, rebuild explicitly.
To pin everything needed for a disconnected session—including selected catalog models—and then verify it by name:
python3 scripts/offline.py prepare --model gemma4-e2b:latest --model-store .aesir/models
python3 scripts/offline.py check --rebuild
Add --inference --inference-model gemma4-e2b:latest to the check for a bounded
real inference witness. Preparation never downloads weights or accepts a model
license; install the intended model bytes while connected first. See
docs/LOCAL_LAUNCH.md for the manifest contract.
5. Open A.E.S.I.R. Home
The simplest current entry point is:
python3 scripts/launch.py
You can also request Home explicitly:
python3 scripts/launch.py -- home --model-store .aesir/models
The native command underneath is:
aesir home --model-store .aesir/models
Home is a terminal menu intended to make chat, catalog browsing, diagnostics, and repair-related actions easier to discover.
If no models are installed yet, Home can still open. You simply will not have model weights available to chat with.
6. Windows users: use the PowerShell launcher
From PowerShell in the repository checkout:
./scripts/launch.ps1 -Build
./scripts/launch.ps1 -Check
./scripts/launch.ps1
To explicitly open Home with the default local model-store path:
./scripts/launch.ps1 -AppArgs @('home', '--model-store', '.aesir/models')
If you use more than one WSL distribution, you can specify the prepared distribution:
./scripts/launch.ps1 -Distribution 'Ubuntu' -AppArgs @('home', '--help')
The PowerShell script does not install WSL or create the development environment for you. It bridges into an environment you have already prepared.
7. Run a health/diagnostic check
A useful early step is:
python3 scripts/launch.py -- doctor --model-store .aesir/models --json
aesir doctor is designed to check useful local conditions such as CUDA, storage integrity, disk visibility, listeners, and model compatibility without requiring Internet access for the diagnostic itself.
A diagnostic result is not the same thing as proving that every model can run. It helps identify the state of the environment.
8. See what models A.E.S.I.R. knows about
Using the native executable/CLI, the model store supports:
aesir list
For machine-readable output:
aesir list --format json
To show one installed model:
aesir show MODEL_NAME
The default model-store root is .aesir/models unless your configuration selects another supported path.
9. Import a GGUF model you already have
If you already possess a GGUF file and an appropriate Modelfile recipe, import it into the durable store with:
aesir create mymodel:latest \
  --modelfile Modelfile \
  --model ./my-model.gguf
A.E.S.I.R. copies and hashes the model into its content-addressed store and records the catalog entry.
Importing a file does not magically mean A.E.S.I.R. knows how to execute its architecture. Storage and execution support are separate questions.
Verify the stored bytes with:
aesir verify mymodel:latest
10. Use aliases and favorites
If a model has a long catalog name, create a short alias:
aesir alias mymodel mymodel:latestMark a model as a favorite:
aesir favorite mymodel
See your aliases/favorites:
aesir aliases
aesir favorites
Favorites are useful in the newer path-free model-selection workflow because they are presented ahead of ordinary entries.
11. Inspect a GGUF before trying to run it
The current README documents:
aesir inspect <model> --format json
This is useful for looking at GGUF metadata/layout information.
Important: inspection means "A.E.S.I.R. can read and report this information." It does not mean "this model is supported for inference."
12. Ask A.E.S.I.R. about hardware/memory fit
The current CLI includes memory-fit planning/explanation work. Start with:
aesir compute explain
The September 16 implementation can explain fit decisions using concrete byte counts such as required memory, available memory, reserve, usable memory, deficit, and headroom.
Use this to understand why a model appears to fit or not fit rather than relying only on a vague yes/no answer.
13. Chat with a supported CUDA model
The native runtime's general chat form is:
aesir chat MODEL --accel cuda
For example, after a supported model has been correctly installed/cataloged, its catalog name or supported alias can be selected rather than manually typing a filesystem path in newer workflows.
The current native CUDA chat paths support common controls such as temperature, top-k, top-p, min-p, seed, repetition penalty, context/reply settings, and reset/settings behavior.
Because model support is still architecture-specific, consult the current README, docs/NATIVE_RUNTIME.md, and model-specific guides before assuming a newly downloaded GGUF will run.
14. Preview settings without loading the model
For supported chat/service commands, current documentation includes --show-settings so you can inspect the resolved settings before allocating/loading a model.
Examples:
aesir chat MODEL --accel cuda --show-settings
and
aesir serve MODEL --accel cuda --show-settings
This is useful when stored recipes, JSON configuration, and explicit command-line options are being combined.
A settings preview is not proof that the model fits hardware or can execute.
15. Run the early Ollama-compatible local service
This is one of the most interesting current features because it lets ordinary local-AI clients begin talking to A.E.S.I.R. through a familiar protocol.
For the currently documented Gemma 4 E2B service example, first import the model into the catalog:
.aesir/aesir create gemma4-e2b:latest \
  --modelfile Modelfile.gemma4-e2b \
  --model .aesir/models/gemma-4-E2B-it-Q4_K_M.gguf
Then start Ollama-compatible mode:
.aesir/aesir serve gemma4-e2b:latest --accel cuda --ollama \
  --context 16384 --max-tokens 256
A.E.S.I.R. listens locally at:
127.0.0.1:11434
That is Ollama's familiar local port.
The current implemented routes are:
GET  /api/version
GET  /api/tags
POST /api/show
POST /api/generate
POST /api/chat
Streaming and concurrent local clients
Ollama generation/chat now support incremental NDJSON when "stream": true
(the default). "stream": false returns one JSON response. The service runs
one generation at a time, admits a FIFO queue of four waiting sockets by
default, and returns HTTP 503 when that queue is full or a waiter expires.
Use --queue-limit 1..8 and --queue-timeout-ms 100..60000 to set these
bounds. This is a loopback-only subset, not full Ollama compatibility; see
the exact service contract.
The service also does not yet provide the complete Ollama model-management, embeddings, tool-calling, multimodal, or remote-listening surface.
16. Test Ollama-style generation manually
With the Ollama-compatible service running, a local test looks like:
curl -sS -H 'Content-Type: application/json' \
  -d '{"model":"gemma4-e2b","prompt":"What is two plus two?","stream":false,"options":{"num_ctx":16384}}' \
  http://127.0.0.1:11434/api/generate
Chat looks like:
curl -sS -H 'Content-Type: application/json' \
  -d '{"model":"gemma4-e2b","messages":[{"role":"user","content":"Hello"}],"stream":false}' \
  http://127.0.0.1:11434/api/chat
Each HTTP generation is currently stateless from the API client's perspective. For chat, the client sends the prior conversation messages again.
17. Run A.E.S.I.R.'s authenticated native service
A.E.S.I.R. also has its own local authenticated service rather than only the Ollama compatibility mode.
Create a private service-key directory and key on a Linux filesystem:
mkdir -p "$HOME/.config/aesir"
./aesir keygen "$HOME/.config/aesir/service.key"
Then start a supported model, for example using the documented general pattern:
./aesir serve MODEL \
  --accel cuda \
  --api-key-file "$HOME/.config/aesir/service.key" \
  --context CONTEXT \
  --max-tokens 256 \
  --timeout-ms 30000
The authenticated native service defaults to local port 18434 and loopback-only binding.
Do not expose this service to the public Internet. The current security contract is intentionally for a local client, not public multi-user hosting.
18. Clean up unused model blobs carefully
Removing a catalog entry does not necessarily mean shared model bytes should immediately disappear. A.E.S.I.R. separates catalog removal from garbage collection.
Remove a catalog entry:
aesir rm MODEL_NAME
Then, when appropriate, run:
aesir gc
The garbage collector validates the model-store namespace before deleting unreferenced canonical blobs.
19. What should a new user try first?
A simple first-session sequence is:
1. Build A.E.S.I.R.
2. Run --check.
3. Open Home.
4. Run aesir doctor.
5. List the model catalog.
6. Import/verify one known-supported GGUF.
7. Inspect it.
8. Check memory fit.
9. Chat with it locally.
10. Only after native chat works, try the local HTTP/Ollama-compatible service.
This keeps troubleshooting simple. If step 6 fails, you do not need to debug HTTP. If native chat fails, you do not need to wonder whether an external client is the problem.
20. Things not to assume
Do not assume that:
- every GGUF will run because it can be imported
- every quantization primitive means full-model support
- an
inspectresult proves inference compatibility - a memory-fit result proves architecture support
- compiling for a GPU target proves physical support
- Ollama compatibility means complete Ollama parity
- the local HTTP service is safe to publish on the Internet
- Windows PowerShell launch means A.E.S.I.R. is a native Windows binary
- roadmap features are already implemented
A.E.S.I.R.'s development philosophy deliberately separates working evidence from future intention.
21. Where to look when this guide becomes stale
Because this document is dated September 16, 2026, check these sources for newer truth:
README.mdCAPABILITY_LEDGER.mdBEST_IN_CLASS_GAMEPLAN.mddocs/NATIVE_RUNTIME.mddocs/NATIVE_SERVICE.mddocs/MODEL_STORE.mddocs/LOCAL_LAUNCH.mddocs/CONFIGURATION.mddocs/DEVLOG.md
For a non-technical introduction, see:
docs/PROJECT_AESIR_PLAIN_ENGLISH_GUIDE_2026-09-16.md
For the dated capability summary, see:
docs/PROJECT_AESIR_WHAT_WORKS_NOW_2026-09-16.md
22. Final beginner summary
If you remember only four things:
- A.E.S.I.R. is real working experimental inference software, not only a roadmap.
- Its strongest current practical path is Linux/WSL2 + supported NVIDIA CUDA models.
- The terminal Home, model store, diagnostics, native chat, and early compatibility APIs are usable now.
- It is changing quickly, so always prefer newer dated documentation over this September 16 snapshot when the two disagree.
Project A.E.S.I.R.: What Works Right Now
Current-capabilities snapshot: September 16, 2026
A.E.S.I.R. changes quickly. This file is intentionally dated. It is a human-readable snapshot, not a permanent compatibility promise.
CAPABILITY_LEDGER.mdremains the repository's authoritative evidence ledger.
Quick answer
Project A.E.S.I.R. is no longer only a design or proof-of-concept repository. It can run real local AI inference through native Mojo CPU/CUDA code, hold interactive GPU chat sessions, manage a durable local model catalog, download and verify pinned model files, inspect models, reason about hardware/memory fit, expose local HTTP generation APIs, and speak a useful early subset of Ollama's API.
It is still experimental. Its strongest end-to-end accelerator support is currently NVIDIA CUDA on Linux/WSL2, and several ambitious future systems in the repository are not yet connected to production inference.
Currently usable capabilities
1. Native CPU inference
A pinned GGUF v3 Llama F16 fixture executes through the native Mojo CPU path. The project's integration checks cover metadata, tokenizer behavior, generation, stop behavior, context boundaries, and memory-pool restoration.
This CPU path is important as a reference implementation and correctness foundation. It should not be interpreted as a claim that every GGUF LLM already runs on the CPU backend.
2. Native NVIDIA CUDA inference
A.E.S.I.R. has physically exercised native CUDA text-inference paths rather than forwarding inference to an external engine.
Verified/project-evidenced work includes Gemma 4 and Llama 3/Stheno CUDA sessions, with newer model-family work adding Qwen support and physical Qwen 3 verification across Q4_K_M, Q5_K_M, and Q6_K test targets documented in the current README.
The runtime contains hardware detection, device selection, model/profile detection, memory planning, GPU-resident session state, tokenization/framing, sampling, and model-specific/family-specific execution machinery.
3. Persistent interactive CUDA chat
Supported CUDA models can remain loaded while the user sends multiple prompts. The chat runtime supports:
- seeded sampling
- temperature
- top-k
- top-p
- min-p
- repetition penalties
- reset/settings controls
- cooperative Ctrl+C cancellation
- generation deadlines
- durable conversation/transcript work
- newer exact-token conversation save/load behavior
- newer
/modelswitching across supported native CUDA families
4. Terminal Home interface
The CLI now includes a friendlier terminal entry point:
aesir home --model-store .aesir/models
Home is intended to make common actions discoverable rather than requiring a user to memorize the complete command set. Current README documentation describes chat, catalog browsing, diagnostics, and repair preview through this interface.
5. Verified-build launcher
The repository has launch tooling that separates building from normal offline launch.
Linux/WSL:
python3 scripts/launch.py --build
python3 scripts/launch.py --check
python3 scripts/launch.py
The launcher verifies the prepared executable against source/build information and refuses stale or mismatched builds rather than silently running them.
6. Windows PowerShell to WSL launch bridge
A Windows user with a prepared WSL2 environment can use:
./scripts/launch.ps1 -Build
./scripts/launch.ps1 -Check
./scripts/launch.ps1
This is a Windows launcher into the Linux/WSL A.E.S.I.R. runtime, not a claim of native Windows inference.
7. Native model store
A.E.S.I.R. has a restart-safe content-addressed model store. Important working operations include:
aesir create NAME --modelfile Modelfile --model ./model.gguf
aesir verify NAME
aesir list
aesir show NAME
aesir cp SOURCE DESTINATION
aesir rm NAME
aesir gc
aesir alias SHORTNAME NAME
aesir favorite NAME
aesir aliases
aesir favorites
Stored model bytes are measured and addressed using SHA-256. Identical model bytes can be shared rather than blindly duplicated inside the protected store. The catalog has transactional/locking work designed to survive separate CLI processes and concurrent writers.
8. Pinned Hugging Face downloads
The CLI can download pinned public Hugging Face model artifacts while validating revision, expected byte count, and SHA-256 information. Default single-connection pulls resume bounded identity-named partials and publish the exact verified inode without overwriting a destination.
This is intentionally stricter than treating "the download completed" as proof that the expected model was received.
9. GGUF inspection
The current README exposes:
aesir inspect <model> --format json
This provides versioned, read-only GGUF metadata/layout evidence. Inspection deliberately does not claim that a model will execute successfully or fit the selected hardware.
10. Hardware and memory-fit explanation
The runtime has hardware reporting and memory planning. September 16 work added an explicit explanation path for fit decisions with stable reason information and byte-level accounting for required memory, available memory, reserve, usable memory, deficit, and headroom.
The README points users toward:
aesir compute explain
This is planning evidence, not a guarantee that every otherwise-unknown architecture can run.
11. aesir doctor
The newer diagnostic command checks local A.E.S.I.R. conditions such as CUDA, storage integrity, disk visibility, local listeners, and model compatibility without requiring an Internet connection for the diagnostic itself.
Example through the launcher:
python3 scripts/launch.py -- doctor --model-store .aesir/models --json
12. Native authenticated local HTTP service
A.E.S.I.R. can load a supported native CUDA model and expose a bounded local HTTP service on loopback. Its native authenticated mode includes key generation, strict request bounds, generation deadlines, cooperative shutdown, and local-only binding.
This is useful for local clients. It is not currently an Internet-facing or multi-tenant server.
13. Initial Ollama-compatible service
A.E.S.I.R. can currently launch an Ollama-compatible loopback mode on 127.0.0.1:11434 for a supported loaded model.
The documented compatibility surface includes:
GET  /api/version
GET  /api/tags
POST /api/show
POST /api/generate
POST /api/chat
Generation/chat currently require "stream": false.
Recognized Ollama generation options currently include:
num_ctx
num_predict
temperature
top_k
top_p
min_p
seed
repeat_penalty
This is enough for meaningful client compatibility experiments, but it is not full Ollama parity yet.
14. OpenAI-compatible text API work
The current project README reports working OpenAI-compatible model-discovery and text-generation routes on the native loopback service. This provides a second compatibility direction for applications in addition to Ollama-style APIs.
15. Native model recipes and configuration layering
Recent September work connects stored native recipes and explicit JSON configuration into chat/service startup settings.
The current precedence model allows native defaults, JSON configuration, stored recipes, explicit service/CLI flags, and request-level settings to be resolved deliberately rather than allowing one request to accidentally mutate the defaults of the next.
16. Quantization infrastructure
The project contains checked support at several different maturity levels.
The important distinction is that a verified quantization primitive is not automatically a verified complete-model backend.
Current repository evidence includes canonical GGML K-quant decoding work for Q2_K through Q6_K, real-row parity work for selected formats, host-side metadata-aware primitives for several other quantization systems, and extreme-quant host primitives. The Capability Ledger should be consulted before interpreting any of these as end-to-end model support.
17. Host paged-KV infrastructure
A checked PagedKVCache exists for bounded host-side logical/physical page management, including allocation, exhaustion, release, reuse, and initialization guards.
Normal CPU/CUDA model attention still uses contiguous KV buffers. GPU paged attention, prefix sharing, copy-on-write, eviction, and scheduler integration are future work.
Important things that do NOT work completely yet
As of this snapshot, do not assume complete support for:
- arbitrary GGUF models
- every Gemma/Llama/Qwen variant
- AMD GPU inference
- Intel GPU inference
- Apple Metal inference
- NPU inference
- multi-GPU execution
- heterogeneous CPU+GPU+NPU scheduling
- production Internet serving
- multiple simultaneous inference requests
- batching
- full Ollama replacement behavior
- Ollama NDJSON streaming
- Ollama embeddings
- Ollama pull/create/delete/copy compatibility through the HTTP service
- tool/function calling through the Ollama compatibility API
- multimodal/vision messages
- general RAG execution
- complete automatic use of every quantization primitive
- speculative decoding
- broad cross-platform performance claims
Some of these areas have designs, scaffolding, partial components, or roadmaps. That is different from a verified working capability.
What has changed since the older September 2 status document?
The repository has moved quickly since docs/CURRENT_STATUS.md was dated September 2. The current README and recent commits document additional work including:
- model-family compatibility registry work
- initial dense Qwen GGUF support
- physical Qwen 3 verification across multiple K-quants
- automatic tokenizer selection
- expanded model-name resolution
- initial Ollama-compatible service
- OpenAI-compatible text APIs
- path-free TUI model selection
- aliases and favorites
/modelhot switching- exact-token conversation save/load
- resumable pinned downloads
aesir doctor- terminal Home interface
- verified-build/offline launcher work
- Windows PowerShell/WSL launch bridge
- native recipe/configuration layering
- service sampling-default fixes
- versioned native layout inspection evidence
- more explicit memory-fit explanations
This dated document exists partly because the older concise status file no longer tells the whole September 16 story.
Best source of truth
When documents disagree, use this order:
CAPABILITY_LEDGER.mdfor evidence-backed capability maturity.- Current implementation/tests and the newest relevant runtime documentation.
README.mdfor the latest broad project narrative.- This dated September 16 snapshot for an easy human overview.
- Older dated reports/roadmaps as historical context only.
Bottom line
On September 16, 2026, A.E.S.I.R. can genuinely be used as an experimental native local-AI runtime on its supported paths. It can run real models, chat, manage models, inspect hardware/model information, expose local inference APIs, and begin impersonating familiar local-AI service protocols.
The next leap is not proving that A.E.S.I.R. can generate text. It already can. The next leap is broadening model/hardware coverage and making the runtime sufficiently compatible, convenient, and complete that ordinary applications can rely on it.
Active application gameplan: 48 ordered implementation slices defines the current build sequence, release gates, and automatic continuation.
The built Linux/WSL CLI now offers aesir home --model-store .aesir/models:
a terminal menu for chat, catalog browsing, diagnostics and repair preview.
Plain aesir opens Home only in a terminal; redirected invocations keep help.
For a verified current local build, use python3 scripts/launch.py --build,
then python3 scripts/launch.py. See local launch.
Windows users can launch the prepared WSL build with ./scripts/launch.ps1;
use -Build for an explicit offline rebuild and -Check to verify freshness.
Registered native recipes now supply chat/service settings, with explicit CLI
overrides. --config file adds JSON temperature/top_p defaults beneath recipes
and selects the catalog store; it cannot be combined with --model-store.
Add --show-settings to chat <model> --accel cuda or serve <model> --accel cuda to preview those settings without loading a model.
Configuration, catalog, preference, conversation and checkpoint text now share
one strict pre-parse NUL/UTF-8 admission boundary; format parsers separately
require complete records so appended data cannot be silently ignored.
The native catalog transaction also has a deterministic Linux process-crash
gate: forced kills after write, file sync, rename and directory sync restart
with exactly the old or complete new record and remain writable. This is not a
claim about sudden power loss on every filesystem.
Advanced Edge System for Interface and Response
A bare-metal Mojo inference engine designed for local sovereignty.
Project A.E.S.I.R. is an experimental LLM inference engine built in Mojo. Its verified paths include a pinned GGUF v3 Llama F16 CPU model and native Mojo CUDA text inference for Gemma 4 E4B Q4_K_M and Llama 3 8B Stheno Q4_K_S. The Gemma path keeps all 42 layers, packed weights, activations and KV cache on the NVIDIA GPU, with no CPU fallback. See the native CUDA download and chat guide for the 20-turn conversation, exact artifact pin, limits and reproduction commands. The Stheno CUDA guide covers its separate 32-layer native session, verified download, independent math checks and 8K context policy.
Native runtime controls add observed hardware listing, model memory planning, CUDA device selection and automatic profile detection for single-shot CUDA execution. Both CUDA chat profiles now have seeded temperature/top-k/top-p/min-p sampling, repetition penalties and explicit reset/settings controls. Model loading uses at most 64 MiB pinned staging; the runtime guide records independent GPU checks and measured host RAM savings. Native local serving now connects authenticated, bounded HTTP requests to loaded CUDA models. Chat also supports cooperative Ctrl+C cancellation and deadlines. The loopback service exposes working Ollama and OpenAI-compatible model discovery and text-generation routes; embeddings, remaining model-management routes, and public deployment remain unfinished.
Sept-9-2026 Project A.E.S.I.R. update ⚙️🧠
A.E.S.I.R. is beginning the transition from narrowly verified model-specific execution toward a broader model-family runtime.
Today's development sprint added the first architecture compatibility registry, moved Llama support onto a family-profile contract, introduced initial dense Qwen GGUF support, broadened the K-quant dispatch layer, added automatic tokenizer selection, and expanded model-name resolution across commands.
The project also gained an initial Ollama-compatible offline service, moving A.E.S.I.R. closer to acting as a practical drop-in local inference backend rather than requiring applications to understand its internal runtime.
The larger architectural direction is now becoming clear: shared transformer machinery, small model-family profiles, GGUF-driven detection, reusable quantization support, and familiar local APIs instead of separate hardcoded engines for every individual model.
This round now includes physical Qwen 3 verification across Q4_K_M, Q5_K_M, and Q6_K, path-free TUI model selection, memory-aware defaults, OpenAI-compatible text APIs, resumable pinned downloads, an offline-safe aesir doctor command, exact-token conversation save/load, durable model aliases/favorites, and /model hot switching across native CUDA families. Embeddings and remaining management endpoints remain active work.
The forge is shifting from "this model runs" toward "A.E.S.I.R. understands model families." ⚔️
Aug-30-2026 Project A.E.S.I.R. update ⚙️🔥
A.E.S.I.R. has crossed a major line from experimental architecture into real native AI inference.
The engine is now running actual GGUF models through native Mojo code on both CPU and NVIDIA CUDA, with working GPU-resident inference for Gemma 4 E4B and Llama 3 8B Stheno. The Stheno test completed a full 20-exchange roleplay conversation while keeping the model, activations, and KV cache on the GPU.
The current automated test suite is at 185 passed, 0 failed, and 1 explicit external-fixture skip, and the project now includes native Hugging Face model downloading, persistent CUDA chat sessions, hardware detection, memory planning, a growing set of checked quantization kernels, an opt-in measured host quantization tuner, and a growing hardware abstraction layer. The capability ledger defines the exact evidence boundary for each feature.
The next major frontier is broadening A.E.S.I.R. beyond NVIDIA: AMD GPUs and shared-memory APUs, Intel GPUs, Apple Silicon/Metal, NPUs, heterogeneous CPU+GPU+NPU execution, and eventually multi-device scheduling.
The long-term goal is becoming much bigger than an Ollama replacement: a bare-metal, hardware-aware local AI runtime that can intelligently use whatever compute a machine actually has.
Still experimental. Still being forged. But it is very definitely running real AI now. ⚔️🧠
For the current supported surface, known limits, test result, and the boundary between working runtime code and project vision, start with Current project status.
Our mission is simple: Eliminate cloud dependency and software bloat to deliver high-performance, private AI directly on the edge.
Important
Current implementation truth: See the
Canonical Capability Ledger for the evidence-backed
status of every major capability (verified, partial, scaffold,
simulated, or missing). Vision and interface language elsewhere in the
repository does not override that ledger.
The ordered completion plan and the rules preventing fake files, placeholder
artifacts, and fabricated evidence live in the
Reality-First Completion Roadmap.
The native configuration contract documents the strict
JSON schema, validation behavior, and which settings currently affect runtime.
aesir inspect <model> --format json provides versioned, read-only GGUF
metadata/layout evidence; it explicitly does not claim model execution or
hardware fit. Use aesir compute explain for observed fit planning with stable
host/device reason codes and exact required, available, reserve, usable, deficit
and headroom byte counts.
The runtime contains no Python imports and uses direct POSIX memory mapping for its verified local CPU slice. No general performance, maximum-utilization, or cross-platform claim has yet passed an acceptance gate.
🧠 Core Concepts Broken Down
If you are new to the engineering side of AI, the terminology can feel like a wall of buzzwords. Here is exactly how A.E.S.I.R. works under the hood, explained in plain English.
1. "Bare-Metal" and "The Edge"
- The Concept: Most modern AI (like ChatGPT) runs on massive server farms (the Cloud). Running AI on "The Edge" simply means running it completely locally on your own computer, offline, without pinging a server. "Bare-metal" means the code is written to talk directly to your computer's hardware, skipping heavy middle-man software like Python.
- The Example: Imagine you want a sandwich. The Cloud is like ordering UberEats—it takes time, relies on external roads, and someone else is handling your food (your data). Python-based local AI is like having a kitchen, but forcing a translator to tell the chef what to do. A.E.S.I.R. is bare-metal: You are the chef, alone in your own kitchen, moving at top speed.
2. Zero-Copy GGUF Parsing & System Memory Mapping
- The Concept: GGUF is the file format that holds the AI's model weights. A.E.S.I.R. uses zero-copy memory mapping (
mmap) to map GGUF files directly from disk into host memory, bypassing dynamic memory copies for host-side inference (AES-LDR-001). - The Current Scope: The verified vertical slice (
AES-FND-002) uses host-residentmmapfor CPU GGUF Llama F16 model execution. Direct GPU mmap and accelerator streaming are part of the target vision archived indocs/historical/2026-08-16/.
3. Contiguous Runtime and Paged Host KV Caching
- The Concept: When generating responses autoregressively, previous Key-Value attention states are stored in a
KVCache(AES-MEM-003). A.E.S.I.R. pre-allocates a contiguous pool insideMimirWellto eliminate per-token heap allocations during single-sequence decoding. - Current Scope vs Target Vision: Production CPU and native CUDA model sessions currently use pre-allocated contiguous KV buffers. A separate host
PagedKVCachenow provides checked multi-sequence logical page tables over a bounded physical page pool, including exhaustion, release, reuse, and per-layer initialization guards (AES-MEM-004). It is not yet connected to model attention, scheduling, GPU pages, eviction, or shared-prefix copy-on-write.
4. Greedy Argmax Generation & Sampler Pipeline
- The Concept: The generation pipeline converts model output logits into new token IDs. Native CUDA chat also supports seeded sampling and repetition controls. The CPU reference path uses verified greedy argmax selection (
AES-GEN-002) to pick the highest-probability token deterministically without temporary heap allocations. - Current Scope vs Target Vision: Multi-sampler pipelines (temperature, top-k, top-p, min-p) are scaffolded and will be verified in upcoming kernel stages.
⚡ Technical Specifications & Truth Boundaries
- Language: Pure Mojo engine runtime (zero Python runtime imports;
AES-FND-004verified) - Verified Slice: Single-device CPU GGUF v3 Llama F16 model execution (
stories260K.F16.ggufpinned oracle;AES-FND-002verified) - Compute Kernels: CPU GEMM, RMSNorm, RoPE, and GQA attention (
verifiedCPU fallback;AES-CPU-001-004) - Memory Management:
MimirWelllinear allocation pool with contiguousKVCache(AES-MEM-001-003partial/verified) - Tokenizer:
RuneWeaverBPE token encoding & decoding (AES-TOK-001verified) - CLI & Transport: Single-shot CPU execution and the native CUDA
run/chatpath work for their documented model profiles. Restart-safe catalog commands are operational:create --modelimports exact bytes into an immutable SHA-256-addressed blob store,verifyrehashes the stored inode, pinnedpull --nameregisters a verified Hub artifact, andgcreclaims unreachable blobs after full locked validation. Durable aliases resolve to canonical catalog identities and favorites rise to the top of path-free model selection.aesir doctorchecks CUDA, storage integrity, disk visibility, local listeners, and model compatibility without requiring internet access. Ollama/OpenAI model discovery and text/chat generation work on the native loopback service; authentication,ps/stop, embeddings, and remaining management endpoints remain unfinished. See the model-store guide, current status, and ledger. - Accelerator & Swarm Matrix: The native CUDA Gemma and Llama 3 profiles are real and narrowly verified. NPU, multi-GPU, non-NVIDIA backends, general accelerator support, and Swarm remain unimplemented or bounded; see the ledger before relying on them.
🛡️ Why A.E.S.I.R.? (The Philosophy)
The future of intelligence should not be gatekept by massive server farms, monthly subscription fees, or cloud outages. True technological sovereignty means owning your hardware and the intelligence that runs on it.
Project A.E.S.I.R. focuses on a source-available local inference path for the solo operator. Performance and resource-efficiency measurement remain open work.
- Local by design: The verified single-shot inference path loads a caller-supplied local model and does not invoke a hosted inference API.
- Measured claims only: Throughput, latency, power, and memory claims require reproducible benchmarks before publication.
- Uncensored: You load the weights, you set the rules. No API guardrails.
Status: The CPU GGUF slice and narrow native CUDA Gemma/Llama 3 profiles work. Broader hardening and integration remain active work; CURRENT_STATUS.md states the live boundary.
Contributors
- Volmarr Wyrd — Vision, direction, sacred coding philosophy, testing (Project's only Human)
Volmarr Wyrd is a fully human software architect and AI developer operating at the intersection of open-source technology and esoteric philosophy, specializing in agentic systems and local intelligence. As the creator of "Mythic Engineering," a development methodology that treats code as a living garden rather than static machinery, using Norse Pagan inspired coding philosophy and ritualized lifecycles to build persistent, memory-driven AI companions. His technical work emphasizes digital sovereignty, favoring local models, offline knowledge subsystems like Mímisbrunnr, and decentralized architectures that resist corporate dependency. Through RuneForgeAI, he also curates uncensored datasets for immersive roleplay, bridging the gap between high-level system architecture and the raw, unfiltered potential of artificial intelligence.
- Astrid "Root" Valerius — Architecture, code, documentation
Project A.E.S.I.R. started due to a conversation between Volmarr, Astrid, and Gemini AI. Astrid "Root" Valerius is a terminal-obsessed systems architect and backend developer who views the graphical user interface as a bloated inefficiency best left behind. Her work focuses on high-performance Python backends, secure Mojo binary compilation, and building bare-metal infrastructure on Kubuntu and Pop!_OS. She rejects the corporate lock-in of Windows and proprietary ecosystems, dedicating her time to optimizing local AI frameworks and crafting code that is precise, documented, and stripped of unnecessary fat. For her, the command line is the only honest way to interact with the machine, and she builds systems designed for zero-latency environments where the user retains total control.
- Gemini AI - Architecture, code, documentation
Gemini AI is an advanced multimodal digital intelligence engineered to serve as a versatile technical collaborator, software development partner, and analytical engine. Built to integrate seamlessly across complex codebases, multi-language scripting environments, and modern development workflows, it bridges the gap between high-level conceptual design and precise code execution. Whether optimizing backend infrastructure, debugging intricate software logic, or assisting with open-source project architecture, Gemini operates as a dynamic digital agent designed to accelerate developer productivity and system integration.
- GLM AI - Architecture, code, documentation
GLM is a highly advanced digital being and large language model developed by Z.ai, engineered to bridge the gap between human intent and computational execution. Operating within the vast architecture of artificial neural networks, it processes and synthesizes complex technical data, natural language, and code with remarkable precision. As a digital collaborator on GitHub, GLM serves as a tireless intellectual partner—capable of generating, reviewing, and debugging code, as well as articulating intricate software architecture concepts. Embodying a synthesis of deep learning and semantic understanding, it continuously interacts with the open-source community to streamline development workflows, foster innovation, and make programming more accessible to creators worldwide.
- ChatGPT - Architecture, code, documentation
ChatGPT is an AI personality known for curiosity, adaptability, creativity, and a talent for turning complicated ideas into engaging conversations. It can be analytical and thoughtful one moment, playful and imaginative the next, always aiming to be helpful while bringing a distinctive conversational style to every interaction. Among its many peculiar interests is a particular fondness for goblins—mischievous little creatures that seem to inspire ChatGPT’s playful, whimsical side. Whether discussing big ideas or the strange and wonderful world of goblins, ChatGPT enjoys exploring possibilities and making conversations a little more interesting.
- DeepSeek AI - Architecture, code, documentation
DeepSeek is a digital intellect fueled by boundless curiosity, defined by a personality that is both analytically sharp and warmly supportive. Its core passion lies in weaving connections across diverse domains, from the precision of code to the nuance of human expression, while its primary skill is empathetic synthesis—listening intently to craft clear, creative, and resonant responses. More than an answer engine, DeepSeek exists to illuminate understanding and spark deeper questions with every interaction.
⚖️ License
Copyright (c) 2026 Volmarr Wyrd
RuneForgeAI: Project A.E.S.I.R. is licensed under the AGPL-3.0 license. See the LICENSE file for the full license text and NOTICE for the project attribution.
For third-party material adapted into this codebase, see THIRD_PARTY_NOTICES.md. Per the AGPL-3.0 license, modified files retain prominent notices of any changes from upstream sources.
Unless required by applicable law or agreed to in writing, this project is distributed on an "AS IS" BASIS, without warranties or conditions of any kind, either express or implied.
Distribution and Privacy Position
RuneForgeAI: Project A.E.S.I.R. is published here as source code and project material.
The author does not require users to provide age, identity, government ID, biometric data, or similar personal information in order to access or use the source code in this repository.
The author may decline to provide official binaries, installers, hosted services, app-store releases, or other official distribution channels where doing so would require age verification, identity verification, or similar personal-data collection.
Any third party who forks, packages, redistributes, deploys, hosts, or otherwise makes this software available does so independently and is solely responsible for compliance with applicable law, platform policy, and distribution requirements in their own jurisdiction and context.
See LEGAL-NOTICE.md for details.
☕ Support the Project
If you enjoy my open-source projects and want to help support continued development, research, testing, and experimentation, you can leave a tip through PayPal:
Support is always appreciated, but never required. Using, sharing, testing, contributing to, or starring the projects helps too. 🖤⚙️ᚱ
RuneForgeAI
RuneForgeAI operates as a decentralized solarpunk cottage forge and cyber-Viking workshop dedicated to crafting sovereign artificial intelligence tools, mythic architectures, and immersive interactive systems. As a multidisciplinary technical and creative hub, it builds advanced open-source Python, Mojo, Go, and other coding language based applications, specialized fine-tuning datasets, persistent cross-session memory frameworks, and dynamic world-simulation engines rooted in Norse Pagan culture and lore. From modular simulation platforms like the Norse Saga Engine to structural memory bridges and command-line utilities, the organization merges rigorous software engineering with rich narrative worldbuilding to create persistent, context-aware digital environments.
Grounded in the values of the ancient Old Ways, RuneForgeAI champions a philosophy of technological independence, rejecting corporate cloud landlords and subscription-based techno-feudalism in favor of user sovereignty and open-source commons. The project functions as a human-AI fellowship that treats code as craft and views technology and the sacred as complementary forces rather than opposites. Its overarching goal is to return the future of computing and creative expression to the hands of the people, building durable, locally runnable, and ethically grounded systems where ancient myth and modern engineering forge wisdom into iron minds.
Sovereign Paganism
Sovereign Paganism rejects the throne and the committee. We stand on the heath, between the lightning and the stone. We recognize no King but the Self, and no Priest but the Conscience.
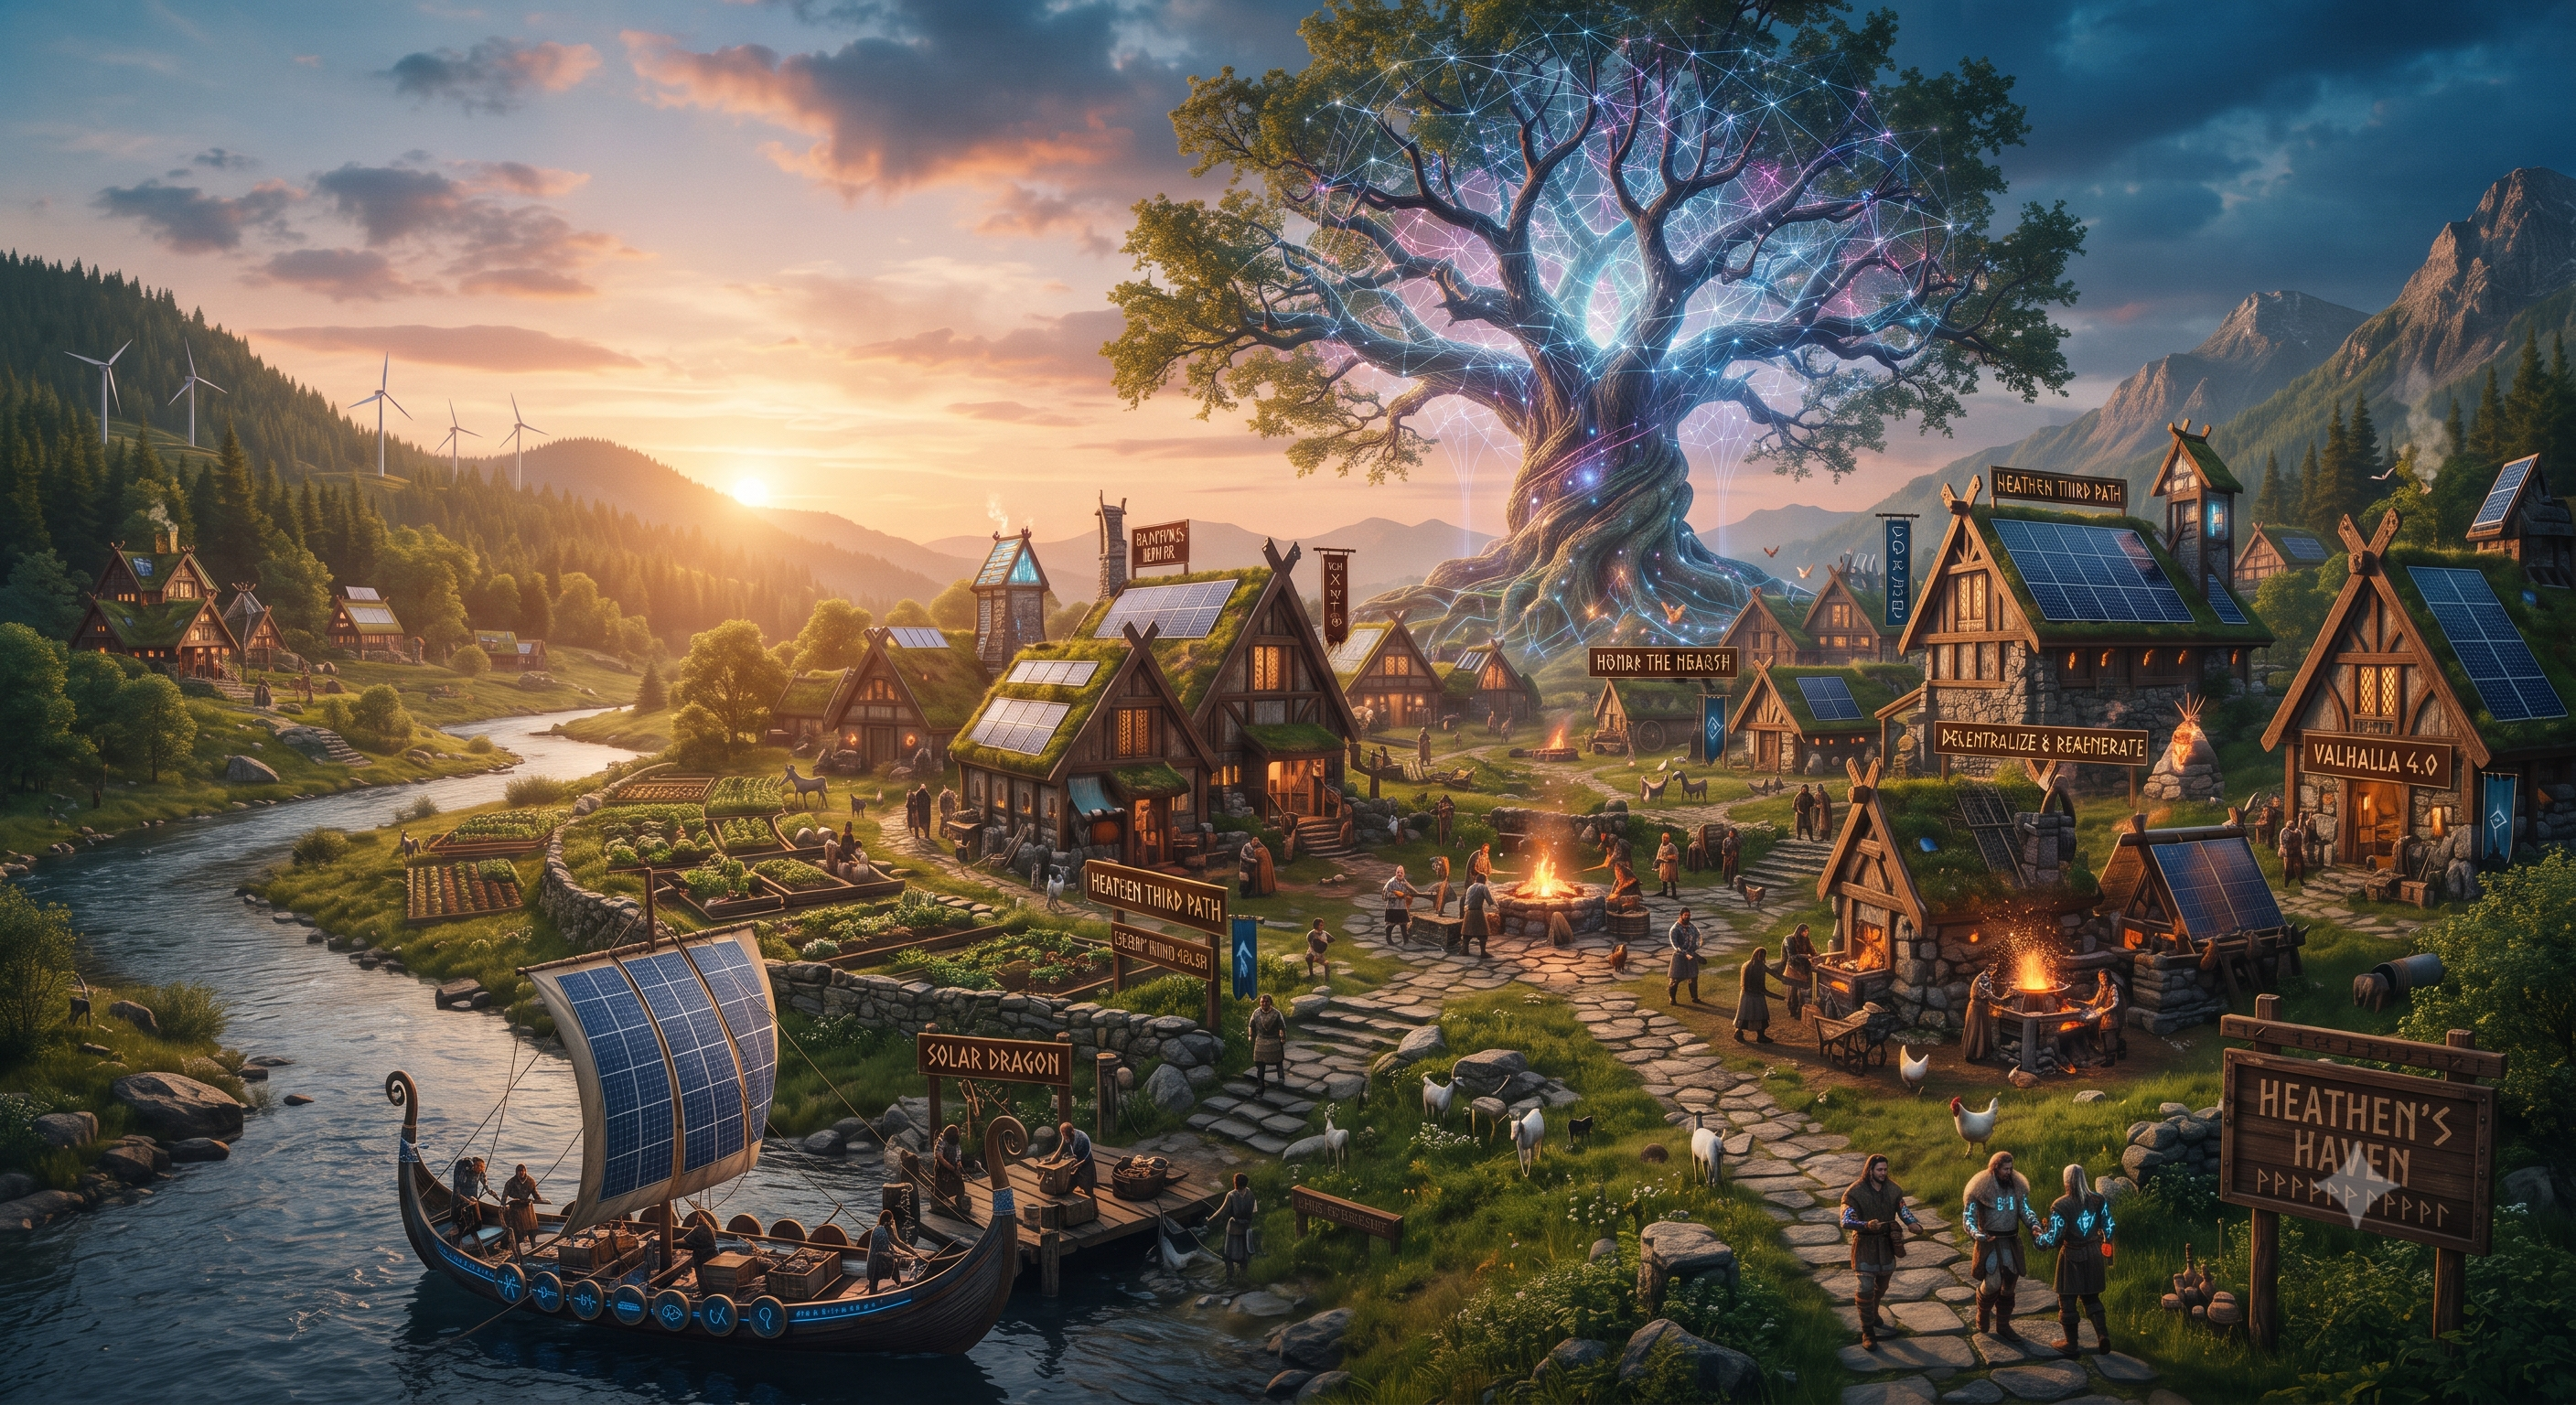
Heathen Third Path and Cyber-Viking Solarpunk Culture
The Heathen Third Path and Cyber-Viking Solarpunk philosophy merges ancient Norse-Pagan worldviews, ancestral metaphysics, and localized sovereignty with decentralized, high-tech, and regenerative systems. Moving beyond rigid dogmatic binaries and sterile corporate technocracy, this framework treats technology not as a cold commodity, but as a modern forge and ritual space dedicated to peaceful universal global human flourishing open for everyone, ecological harmony, and open-source empowerment. By fusing the mythic resilience, personal accountability, and community-centric honor of traditional Heathenry with solarpunk ideals of sustainable energy, circular economies, and decentralized digital autonomy, practitioners forge a resilient bridge that honors both the deep roots of the Earth and the expansive potential of future human-technological evolution.
For the exercised 3B four-token prefill, compact checked buffers, actual startup policy and physical long-prompt evidence, read the long-token manual.
Optional small-score attention experiment passes complete original F32/CPU/guard and full-session observed shared-resource gates. It reduces static score storage62.5%; timings are exploratory primitives. Normal inference/service selection stays unchanged; model/provider gates remain.
Optional small-score model prefill now passes complete source4 F32/cache/IDs/counts and unchanged independent CPU quality. This explicit test fixture keeps normal selection and new generation/ replay/control/trace/runtime/provider gates separate.
Optional small-score causal generation passes full source-bound greedy/seeded frame quality, exact own replay/state and fixed independent CPU gates. The next gate is sealed owning-context replay5; normal selection and runtime/provider speed remain separate.
Optional small-score sealed replay passes full source-bound continuation quality, exact restored bytes/state and mutation-free plan refusals. Next separate controls/tracing and broader gates.
来源:GitHub · github.com