NVIDIA 与 CMU 的 CAKE:让智能体写 GPU kernel,编译器同步进化
Cake from Scratch: Agents Write GPU Kernels
NVIDIA 与卡内基梅隆大学的论文 CAKE(Compiler–Agent co-design for frontier Kernel Evolution,arXiv 2608.12629)提出让智能体编写可静态检查的 CAKE IR 调度语言,由编译器返回定位到资源、角色或流水线阶段的诊断,并在反复失败时反过来修改编译器本身。
In 2022, FlashAttention made the attention layer of a transformer much faster on the same GPU, without approximating anything: it computes exactly the same attention formula, just in a different order, so its results differ from the usual method only by floating-point rounding. It did not find a new formula. It found a better schedule: which piece of data sits in which memory, which part of the chip works on it, and in what order. Three more versions followed, each pairing a better schedule with algorithmic changes suited to the hardware of its day; the last two were written for new GPU generations.
Programs like these are called GPU kernels, and they are where much of the money in AI is spent: every token a large language model (LLM) reads or writes passes through dozens of them. Lately, AI coding agents have started to write kernels too. They propose code, compile it, test it, time it, and try again. On many benchmark tasks this loop now produces correct, fast code. On the hardest kernels, the ones experts write by hand for each new GPU, it still falls short.
CAKE (Compiler–Agent co-design for frontier Kernel Evolution), a paper from NVIDIA and Carnegie Mellon University, argues that improving the agents alone is not enough. Work on kernel agents and work on GPU programming languages have advanced separately, and in the paper’s words, “the gap between them is where expert kernels are lost.” That gap is the world the agents work in: the language they write and the feedback they get back. Today’s agents write raw CUDA or a high-level kernel language, and the environment answers with little more than “it crashed,” “the output is wrong,” or “it took 0.94 ms.” CAKE changes both sides. Agents write a new, checkable language for GPU schedules, and the compiler answers with diagnostics that point at the affected resource, role, or pipeline stage. (The paper does not publish its message format; an example in that spirit, our own: this barrier, in this pipeline stage, is waited on but never signalled.) Then CAKE goes one step further. When agents keep failing in the same way, the compiler itself is changed: the failure becomes a new check, a new language feature, or a corrected performance model.
The headline results, in the paper’s own numbers:
1.144× vs 0.928×Flash-KMeans from a clean startbest kernel after 80M tokens, CAKE IR vs direct CUDA/PTX, relative to a tuned baseline (median of 3 runs, B200)
2.05×Kimi Delta Attention prefillprompt-processing kernel vs the official FlashKDA kernels, averaged over 6 input sizes; validated in end-to-end serving
1.42×–2.12×KNN and KMeans librariesthree kernel families that pick a kernel per input size; averages of 1.418×, 2.116× and 1.803× over 112, 198 and 124 sizes (GB200); single sizes vary more
4 PRsupstream to FlashInferKDA prefill and decode, TinyGEMM, and an Alpha-MoE megakernel; all four merged by September 13, 2026 (per GitHub)
If these labels mean little yet, that is expected; each card gets its own section (§12 for the first, §13 for the second and fourth, §14 for the third). Two words recur everywhere. A shape is one choice of input sizes, such as 32 batches of 65,536 points. When a result covers many shapes, the speedups are averaged with a geometric mean, the standard average for ratios: a 2× win and a 0.5× loss average to 1×, where an ordinary mean would claim 1.25×.
This post explains CAKE from the ground up. It is built from the paper (“CAKE: Compiler–Agent Co-Design for Frontier Kernel Evolution,” arXiv 2608.12629, submitted August 12, 2026), its LaTeX source and figures, and the public sources it cites; hardware background comes from NVIDIA’s documentation and independent measurements, and upstream details from the FlashInfer and FlashLib pull requests and the Kimi-K3 model card, each linked where used. Numbers come from the paper unless we say otherwise. Values we read off a plot are marked “approximate”; numbers we computed ourselves are marked “derived”; our own readings of the evidence are marked as interpretation. Where the paper is silent, we say so, and §16 collects those gaps.
Who this post is for
Most papers about GPU kernels assume you already write them. This post does not. If you know some Python and roughly what a neural network does, you can follow it. We borrow the shape of a much-loved operating-systems textbook, Operating Systems: Three Easy Pieces by Remzi and Andrea Arpaci-Dusseau, and use three of its habits:
- Three pieces. The post has three parts, and each opens with a short dialogue between a Professor and a Student. The dialogues raise the questions and sketch the intuition; every fact is worked out in the main text.
- The crux. Chapters that tackle a real problem name it in a box labelled The crux, so you know what we are trying to solve.
- Asides and tips. Aside boxes hold background you can skip. Tip boxes state a general lesson that outlives this paper.
If you already know GPUs well, skip Part I and start at §5.
The road map
- Part I · The Machine (§1–4): what a GPU kernel is, why speed is mostly about moving data, how modern GPUs turned into asynchronous assembly lines, and what separates an expert’s kernel from a merely correct one.
- Part II · The Language (§5–8): how agents write kernels today and what feedback they get; the menu of GPU languages and why none fits an agent well; CAKE IR, read line by line; and where it came from.
- Part III · The Loop (§9–16): the checks CAKE runs before a kernel ever touches the GPU; one round of evolution; how the compiler itself evolves; the controlled experiment; the production results; turning a tuned kernel into a library; related work; and the limits.
- Epilogue: a closing dialogue, a summary, questions to think about, and annotated sources.
Part I · The Machine — a dialogue
Professor Welcome back. Today: a paper about AI agents that write GPU kernels.
Student I use PyTorch every day and I've never written a kernel. Do I need one?
Professor You use them constantly. Every torch.matmul ends up as a kernel someone wrote. The question is who writes the next ones, for the next GPU.
Student Can't the compiler just generate them? That's what compilers are for.
Professor For simple operations, yes. For the important ones, the fastest code still comes from experts. They know things about the chip that compilers don't decide well yet.
Student Like what?
Professor Like which group of threads loads data while another group multiplies, and how they tell each other "your data is ready." Get that wrong and the program doesn't crash politely. It hangs, or it quietly produces garbage.
Student That sounds miserable to debug. And an AI is supposed to do it?
Professor That's the paper's question. But first you need to see the machine. Let's start with what a kernel actually is.
1. What a GPU Kernel Is
A GPU is a chip built to do the same simple operation on a huge amount of data at once. This section introduces the vocabulary the rest of the post needs: threads, warps, blocks, streaming multiprocessors, and the word kernel itself.
1.1 Many small workers instead of a few fast ones
A CPU has a handful of powerful cores, each built to finish one sequence of instructions as quickly as possible. A GPU makes the opposite bet. It has thousands of simpler lanes, and it wins by keeping all of them busy at once. Nobody cares how long one multiplication takes; what matters is how many finish per second. This is the difference between optimizing for latency and optimizing for throughput.
A kernel is a function that runs on the GPU. You write it once, and the GPU runs one copy per thread, often millions of threads, each working on a different piece of the data. Adding two vectors of a million numbers is the classic first kernel: thread i reads a[i] and b[i], adds them, and writes c[i].
Threads are organized in a hierarchy, and the hierarchy matches the hardware:
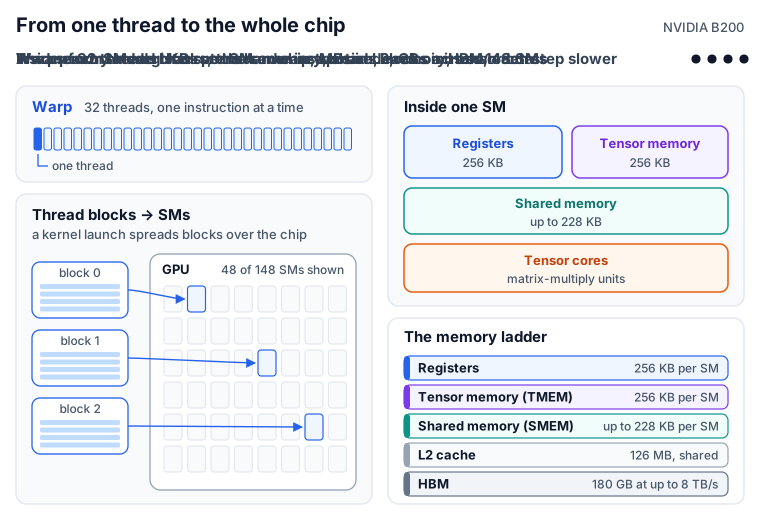
- Warp. NVIDIA GPUs run threads in groups of 32 called warps. The 32 threads of a warp execute the same instruction at the same time, each on its own data.
- Thread block. Warps are grouped into thread blocks (also called CTAs, cooperative thread arrays). The threads of one block run on the same part of the chip and can share a fast scratchpad memory.
- Streaming multiprocessor (SM). The chip is made of many identical SMs. Each SM runs one or more thread blocks at a time, with its own registers, scratchpad memory, and math units. An NVIDIA B200 has 148 SMs.
- Grid. One kernel launch creates a grid of thread blocks, and the hardware spreads them across the SMs.

1.2 Why matrix multiplication is the kernel that matters
Vector addition is easy because every output needs exactly two inputs. Matrix multiplication is different. To compute an output matrix C = A × B, every output element needs a whole row of A and a whole column of B, and every input element is used by many outputs. That reuse is both the opportunity and the difficulty: a good kernel loads each piece of input once and reuses it many times, and a bad one keeps fetching the same numbers from far away.
Almost everything a transformer does is built on matrix multiplications: the projections in attention, the feed-forward layers, the experts in a mixture-of-experts (MoE) model. Modern GPUs have dedicated units for them, called tensor cores, which multiply small matrix tiles in a single instruction. Kernel writers call a matrix multiply a GEMM (general matrix multiply) and the tensor-core operation an MMA (matrix multiply-accumulate, C += A × B). Most of the kernels in the CAKE paper are, at heart, careful ways to keep tensor cores fed.
2. Fast Kernels Are About Moving Data
Here is the first surprise for newcomers: on a modern GPU, doing the arithmetic is rarely the hard part. Getting the numbers to the arithmetic units in time is.
2.1 The memory ladder
A GPU has several kinds of memory, arranged like the rungs of a ladder. The closer a rung is to the math units, the faster it is, and broadly the smaller: the on-chip rungs hold a few hundred kilobytes per SM, the off-chip ones megabytes to gigabytes.
| Rung | Where it lives | Size (B200) | What it is for |
|---|---|---|---|
| Registers | inside each SM | 256 KB per SM, split among its threads | each thread’s working values |
| Tensor memory (TMEM) | inside each SM, new in data-center Blackwell (B200, GB200) | 256 KB per SM | the accumulators of tensor-core matrix multiplies |
| Shared memory (SMEM) | inside each SM | up to 228 KB per SM | a scratchpad that the threads of a block share, programmed by hand |
| L2 cache | shared by all SMs | 126 MB | a hardware-managed cache |
| HBM (high-bandwidth memory, also called global memory) | stacks of DRAM next to the chip | 180 GB at about 8 TB/s | where tensors live |
Where these hardware numbers come from
- Registers (64K 32-bit registers per SM), shared memory (228 KB per SM, at most 227 KB per block) and the 126 MB L2: NVIDIA’s Blackwell tuning guide and the compute-capability tables of the CUDA programming guide. The tuning guide states the L2 size for GB200; Chips and Cheese measured the same 126 MB on a B200.
- Tensor memory: the PTX ISA describes 128 rows × 512 columns of 32-bit cells per CTA, which is 256 KB.
- HBM: 180 GB at up to 8 TB/s per B200 (NVIDIA reference architecture). Dense BF16: an 8-GPU HGX B200 is rated at 36 PFLOPS with sparsity, and dense is half of that, so 2.25 PFLOPS per GPU.
- SM count: NVIDIA’s datasheets do not list it. The 148 comes from the FlashAttention-4 paper and independent measurements. The Blackwell GPU in a GB200 is a slightly larger configuration (186 GB of HBM, 2.5 PFLOPS dense BF16).
Eight terabytes per second sounds enormous until you compare it with the math. The tensor cores of a B200 can do about 2.25 thousand trillion (2.25 × 10¹⁵) dense BF16 operations per second. (BF16, or bfloat16, is a 16-bit floating-point format. Deep learning uses it because it halves memory traffic compared with ordinary 32-bit floats, FP32, at a loss of precision that networks tolerate; FP8 and FP4 go down to 8 and 4 bits. “Dense” means without the sparsity trick NVIDIA uses to double its headline figure.) Divide one by the other: to keep the tensor cores busy, a kernel must do roughly 280 operations for every byte it reads from HBM (derived). A kernel that does less work per byte spends its time waiting for memory, no matter how clever its math is.
This ratio of operations to bytes is called arithmetic intensity, and the idea that a kernel is limited either by memory bandwidth or by compute, whichever runs out first, is called the roofline model. Adding two vectors does one addition per 12 bytes moved (two 4-byte reads, one write); it will always be memory-bound. A large matrix multiplication can reach thousands of operations per byte, but only if the kernel reuses data well.
2.2 Tiling: the trick behind every fast kernel
The standard way to raise reuse is tiling. Instead of fetching inputs element by element, a thread block copies a tile of A and a tile of B from HBM into shared memory, multiplies them using the tensor cores, accumulates the partial result, and then moves on to the next pair of tiles. Each number fetched from HBM is reused by a whole row or column of the output tile: with 128 × 128 tiles, 128 times instead of once.
Tiling is also the heart of FlashAttention. It computed the same attention as everyone else, but worked through the inputs tile by tile and fused the steps, so the huge intermediate table of attention scores (one number for every pair of tokens) never had to be written to HBM at all.
Tiling raises a new problem: while the block waits for the next tile to arrive, the tensor cores sit idle. The fix is to fetch the next tile while computing on the current one, using two or more tile buffers. This is called double buffering, or more generally software pipelining. It hides memory latency rather than reducing traffic, and later attention kernels lean on it heavily: FlashAttention-3, written for Hopper, is built around overlapping copies with multiplies.
3. The GPU Becomes an Assembly Line
Recent NVIDIA GPUs added hardware that makes tiling and pipelining much faster, and much harder to program. This section walks through that change, because CAKE’s design follows it closely.
3.1 From “every thread does everything” to specialized roles
In older GPU kernels, every warp did every job: load a slice of the tile, wait for the rest of the block, compute, repeat. Each GPU generation since then has added hardware that does one of these jobs on its own, asynchronously, while the threads do something else. You do not need to remember the names below. What matters is the trend: each generation hands one more job to a dedicated unit that works in the background, so the threads stop doing the work and start coordinating it. The names that come back later are TMA (the copy engine), TMEM (the accumulator memory), and the barriers that announce a finished copy.
- Ampere (A100, 2020) added
cp.async, which copies data from global memory into shared memory in the background. Its tensor cores are driven by warp-levelmma.syncinstructions, fed from shared memory byldmatrix. - Hopper (H100, 2022) added the Tensor Memory Accelerator (TMA), a copy engine that moves an entire multi-dimensional tile with one instruction; WGMMA, a tensor-core instruction issued by a warpgroup of four warps; asynchronous transaction barriers (mbarriers that count the bytes of a copy as they land) to signal when a tile has arrived; and thread-block clusters whose blocks can read each other’s shared memory.
- Blackwell (B200, 2024–25) added
tcgen05.mma, a tensor-core instruction that a single thread issues on behalf of the whole block, and tensor memory (TMEM), a dedicated 256 KB per SM that holds the accumulators so they no longer clog the registers. Two neighbouring SMs can even cooperate on one larger multiply (the “2-CTA” mode).
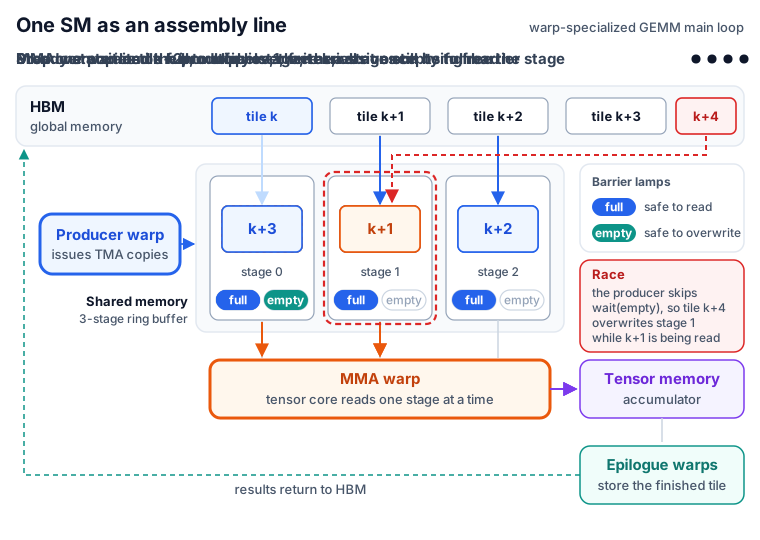
With copy engines and tensor cores that run on their own, the natural design is an assembly line. Some warps do nothing but issue copies (the producer); one warp does nothing but issue matrix multiplies (the MMA warp); others take the finished results, apply any final per-element steps such as scaling or an activation function, and write them out. That last stage is called the epilogue. This design is called warp specialization, and each job is a warp role.

3.2 The handoff: ring buffers and barriers
An assembly line needs a way for stations to hand work to each other. In a warp-specialized kernel, the shared-memory tile buffers form a ring buffer of stages: with three stages, the producer can be filling stage 2 while the tensor cores work on stage 1 and stage 0, just freed, waits for its next tile.
The handoffs use barriers. A barrier is a meeting point set up to expect a certain number of arrivals, its arrival count. A warp that waits on it is held until that many arrivals have happened (for a TMA copy, until all the copied bytes have landed); then the barrier completes its current phase and resets for the next. NVIDIA calls signalling a barrier arriving on it, and the figures use that word.
Each stage has two barriers. The producer arrives on the stage’s full barrier when its copy lands; the consumer waits on full before reading. The consumer arrives on the stage’s empty barrier when it has finished with the stage; the producer waits on empty before overwriting it. Because the ring wraps around, each barrier is reused once per lap, so a waiter must say which lap it is waiting for. The hardware tracks this with a one-bit phase that flips every lap; waiting on the wrong phase either returns too early or never returns.
Two more details matter later. The GPU reaches memory along two separate paths: ordinary loads and stores made by threads (the generic proxy), and the copy engine and tensor cores (the async proxy). Think of two couriers delivering to the same desk: nothing guarantees that one courier sees the other’s deliveries in the order they were made. So when threads write data with ordinary stores that an async operation will then read (for example, values in shared memory that a TMA store or a tensor-core multiply consumes), the kernel needs an explicit proxy fence, or the hardware may reorder the accesses. In the other direction, an async copy’s completion, observed through its barrier, already makes the data visible. And every TMA copy needs a descriptor that encodes the tile’s shape, its strides (how far apart consecutive rows and columns sit in memory), and its layout.
3.3 Why this is so easy to get wrong
Every one of these details is a way to fail, and the failures are cruel:
- A missing wait lets the consumer read a stage before its data arrives. Nothing crashes; the results are simply wrong, sometimes only for some inputs.
- A barrier initialized with too high an arrival count, or a wait on a phase that will never complete, makes a warp wait forever. The kernel hangs, and the only symptom is a GPU that stops responding. (Too low a count, or a stale phase, does the opposite: the wait returns early, and the bug becomes a silent race.)
- A missing proxy fence produces stale data only under particular timing, so the bug appears on one run and vanishes on the next.
- A TMA descriptor whose tile shape disagrees with the shared-memory buffer it fills corrupts memory that belongs to someone else.
Tools exist to help. NVIDIA’s compute-sanitizer can detect some races and out-of-bounds accesses at run time, but only on the inputs you happen to run, and it does not explain which design decision caused the problem. Remember this: a crash or a hang says that something broke, not why. That gap is the subject of Part II.
4. What Separates an Expert Kernel from a Correct One
Put the pieces together and you can see what the CAKE paper means by an expert kernel. Its abstract names three decisions that “separate expert kernels from merely correct ones”:
- Warp specialization. Which warps take which roles: how many producers, how many consumers, whether two groups of consumers alternate (“ping-pong”) so one computes while the other writes results.
- Barrier choreography. How many pipeline stages, which barrier gates which handoff, which phase each wait expects, where the fences go.
- Memory-tier placement. Which data lives in registers, which in shared memory, which in tensor memory, and in what layout, so that the copy engine, the tensor cores, and the output path all agree on where every byte sits.
Together these decisions form the kernel’s schedule: the plan for how the machine is driven, as opposed to what is computed. The math of a matrix multiply fits on one line. The schedule of a fast Blackwell matrix multiply runs to hundreds of lines, and changing one decision usually forces changes in the others.
Summary of Part I
A kernel is a function that thousands of GPU threads run in parallel. Its speed depends mostly on moving data: through a ladder of memories, in tiles, with the next tile loading while the current one is processed. Modern NVIDIA GPUs turned this into an assembly line of specialized warps that hand tiles to each other through barriers. The expert’s art is the schedule (roles, barriers, memory placement), and mistakes in it tend to cause silent wrong answers or hangs rather than helpful error messages.
Part II · The Language — a dialogue
Student So an agent writes a kernel, runs it, and looks at what happened. What's wrong with that? It's how I debug.
Professor What do you look at when your code breaks?
Student The stack trace. The line number. The variable that was None.
Professor Now imagine that for the worst bugs your only feedback is "it froze," "wrong answer," or "it took 0.94 milliseconds." No line, no variable.
Student I'd change things at random and hope.
Professor That's roughly where kernel agents are on the hardest kernels. So, two questions. What language should the agent write in? And what should the compiler tell it when something is wrong?
Student Shouldn't it just write CUDA, like the experts?
Professor CUDA lets you say everything, including every mistake. A higher-level language protects you, but it won't let you say what the expert says. The paper's answer tries to have both: a language that says what the expert says, in a form a compiler can check before anything runs. Let's see how.
5. How Agents Write Kernels Today
Kernel-writing agents arrived quickly. This section describes the loop they share, what that loop is good at, and the feedback problem that CAKE starts from.
5.1 The propose–test–measure loop
The setting was popularized by KernelBench (2025): give a model a PyTorch operator and ask it for a faster GPU kernel that computes the same thing. Since then, many systems have built similar loops, for GPUs and for other AI accelerators.
Many of them borrow the idea of evolution from biology, and CAKE’s title uses the word the same way: keep a set of candidate kernels, ask an LLM to change (“mutate”) the promising ones, test and time every new candidate, keep the fastest correct ones, and repeat. The systems differ in which part of that loop they improve:
- The loop itself. An LLM revises a kernel from compiler errors, test results, or profiler output (AccelOpt, for AWS Trainium; Autocomp, for tensor accelerators; KernelAgent, for GPUs).
- Memory. KernelBlaster adds a persistent knowledge base of past optimizations.
- The search. KernelEvolve and EvoEngineer support evolutionary search over kernel candidates; AVO, from several of CAKE’s authors, replaces fixed mutation rules with coding agents; K-Search separates planning from implementation.
- The model. AutoTriton and CUDA Agent train the model itself with reinforcement learning (learning from rewards such as “correct and fast”).
Underneath the variety, the environment is the same. The agent proposes code, the code is compiled, a numerical test compares its output with a reference, a benchmark measures its latency, and the agent picks the next edit. The CAKE paper’s summary: these methods “evolve the search process, accumulated memory, or model weights while retaining a chosen DSL [domain-specific language] and evaluation environment.”
5.2 What the environment says back
This loop works well for local tuning: try a different tile size, unroll a loop, fuse two operations. It struggles with the decisions from §4, for a reason the paper puts in one sentence: compiler errors, correctness outcomes, and end-to-end timing “never say which program decision caused a synchronization failure, a hardware-contract violation, or a pipeline stall.”
Think about what each signal tells an agent that just rewrote a pipelined kernel:
- A hang. Some warp is waiting on a barrier that never completes. Which barrier? Which stage? Which phase? The process just stops.
- Wrong output. A race, a bad layout, a missing fence, or a plain indexing bug. The test can say which elements differ, not which decision caused it.
- A time. 0.94 ms. Is the kernel limited by memory bandwidth, by tensor-core issue, by a pipeline that is too shallow, by a barrier that serializes two roles? One number cannot say.
- Profiler counters. Some loops also pass along profiler output. It can say that the kernel waits on memory or on the tensor cores, but not which program decision (a stage count, a role split, a buffer placement) made it so.
There is a second, quieter problem. The signals “cannot grow when a frontier workload exposes a missing capability.” If the language cannot express a schedule the new workload needs, every attempt fails for the same structural reason, and the environment never learns from it.
5.3 CAKE’s three commitments
The paper’s observation is that a compiler already contains most of the machinery an expert keeps in their head: “structured operation vocabularies, resource models, legality checks, static analyses, cost models, lowering rules.” (Lowering is the compiler’s translation of a program down to the GPU’s own code; §7.1.) The question CAKE asks is “how to make that machinery agent-facing, and how to improve it when a frontier workload exposes a gap.” Its answer has three parts:
- Agents edit a typed IR, not raw CUDA. An IR (intermediate representation) is a program format designed for a compiler to analyze. CAKE’s is a schedule language in which the hardware decisions are explicit, so they can be inspected before any code is generated.
- The compiler returns localized diagnostics, not a pass/fail bit. Correctness and safety findings point at the affected resource, role, or stage and name the kind of rule that was broken; performance reports estimate the cost and name a broad bottleneck class. Cheap analyses filter candidates before they spend GPU time.
- The harness itself evolves. The harness is everything around the agent that judges its work: checks, tests, and the benchmark (§9). Two of its parts matter here. The verifier reads a schedule and rejects illegal ones before anything is compiled, much like a linter. The cost model predicts how fast a candidate will run without running it, like a weather forecast: cheap, usually close, but you still check the real GPU. When agents keep failing the same way, the harness changes: a new verifier rule, a new primitive (a built-in operation of the language), a recalibrated cost model (refitted to new measurements), or a reusable optimization tactic, each change gated by tests over a corpus of kernels.

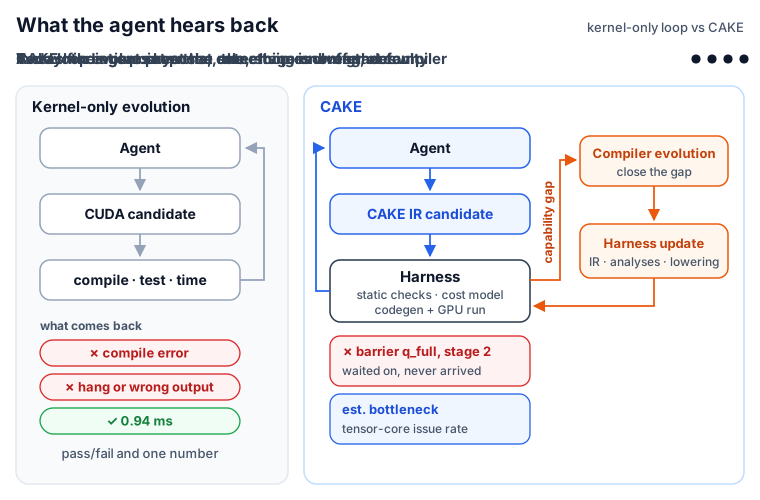
The paper calls the result compiler–agent co-design. The agent’s environment (the language, the analyses, the cost model) is designed around what agents need, is maintained largely by agents, and keeps changing in response to what they run into. The agent itself, its model and scaffold, stays fixed (§10.2). The next three sections cover the first commitment, the language.
6. Which Language Should an Agent Write?
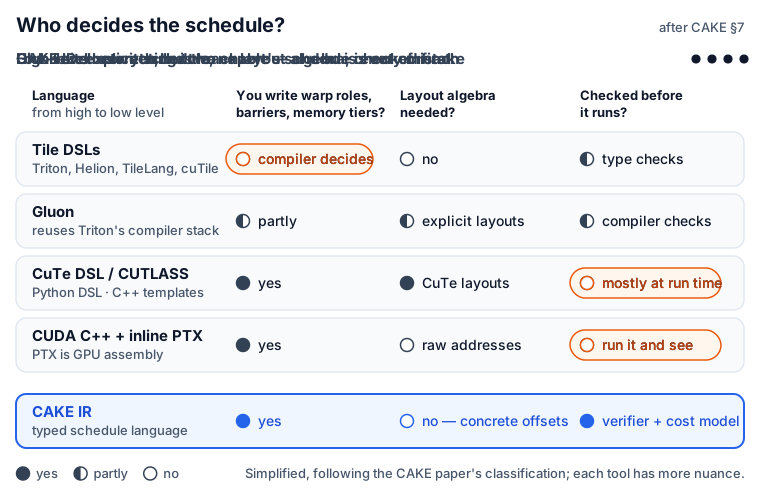
There are many ways to write a GPU kernel. They differ in one question above all: who decides the schedule, the programmer or the compiler? This section walks the menu, using the CAKE paper’s own classification, with one question in mind:
6.1 High-level: tile languages
Triton (2019) made kernel writing accessible by letting programmers think in tiles: you write what happens to a block of a matrix, and the compiler decides how threads, memories, and instructions carry it out. Newer languages such as Helion, TileLang, and NVIDIA’s cuTile follow similar ideas at different levels of abstraction.
This is excellent for humans and gives correct, often fast code. The CAKE paper’s objection is specific: tile languages “hide the warp specialization, barrier choreography, and memory-tier placement that separate expert kernels from merely correct ones.” An agent writing Triton can ask for a pipeline depth (num_stages=3) and, on Blackwell, switch on automatic warp specialization. It cannot say which warps take which role, which barrier gates which handoff, or that the accumulators live in TMEM. The compiler makes those choices, and the agent can only hope they match the expert’s.
6.2 Low-level: CUTLASS, CuTe DSL, and raw CUDA
At the other end is NVIDIA’s CUTLASS library and its Python front end, CuTe DSL. These expose everything the hardware offers. The price is a layout algebra: a mathematical framework for describing how a tensor’s logical coordinates map onto memory and onto threads. Below that is CUDA C++ with inline PTX (NVIDIA’s assembly-like virtual instruction set), where you manage addresses, barrier phase bits, and descriptor encodings by hand.
According to the paper, low-level DSLs such as CuTe DSL “expose that control but demand a layout calculus that makes agent errors both likely and hard to localize.” Many layout mistakes compile. CuTe rejects mismatched ranks and sizes, but a layout with the right shape and the wrong strides or swizzle puts the right numbers in the wrong places, which shows up later as wrong output, or as a slow kernel.
6.3 In between: Gluon
Gluon sits between the two camps. It reuses Triton’s compiler stack but exposes lower-level control over layouts, memory movement, and asynchrony. It moves the dial toward control, and with it toward the burdens of control.
6.4 The gap CAKE aims at
Lay the options side by side and a gap appears. The languages that let you express an expert schedule make you manage layouts and raw details yourself, and many of the worst mistakes (a wait on the wrong phase, a missing fence, a layout with the right shape but the wrong mapping) show up only at run time. The languages that protect you keep most of the schedule in the compiler’s hands, offering at most hints such as a pipeline depth.

7. CAKE IR, Line by Line
CAKE IR is the language the agents write. The best way to understand it is to read some.
7.1 What the schedule states, and what lowering derives
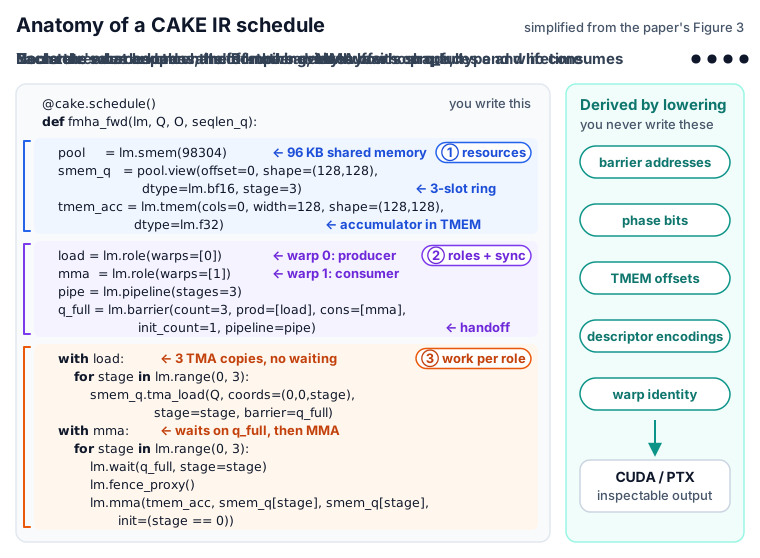
The design rests on a division of labour. In the paper’s words, “a schedule states what is to happen and lowering derives how.” The schedule records which warps take which roles, which buffers are staged how deeply, which barrier gates which handoff, and which instruction form consumes which operand. Lowering, the compiler’s translation down to CUDA and PTX, computes the mechanical consequences: “barrier addresses, phase bits, TMEM offsets, descriptor encodings, and warp identity are all computed from the declarations rather than written out by the agent.”
Here is the fragment the paper uses to show the idea. The paper calls it simply “a CAKE IR schedule fragment”; its name, fmha_fwd (fused multi-head attention, forward pass), and its use of tensor memory suggest it is modeled on the start of a Blackwell attention kernel (our reading):
@cake.schedule()
def fmha_fwd(lm, Q: LM.tma3d, O: LM.tma2d, seqlen_q: LM.i32):
    # declare resources: named resources, not raw addresses
    pool     = lm.smem(98304)
    smem_q   = pool.view(offset=0, shape=(128,128), dtype=lm.bf16, stage=3)
    tmem_acc = lm.tmem(cols=0, width=128, shape=(128,128), dtype=lm.f32)

    # declare roles: warp groups with assigned work
    load = lm.role(warps=[0])
    mma  = lm.role(warps=[1])
    pipe = lm.pipeline(stages=3)
    q_full = lm.barrier(count=3, prod=[load], cons=[mma],
                        init_count=1, pipeline=pipe)

    with load:
        for stage in lm.range(0, 3):
            smem_q.tma_load(Q, coords=(0,0,stage), stage=stage, barrier=q_full)

    with mma:
        for stage in lm.range(0, 3):
            lm.wait(q_full, stage=stage)
            lm.fence_proxy()
            lm.mma(tmem_acc, smem_q[stage], smem_q[stage], init=(stage == 0))
Read it in four steps:
- Signature.
@cake.schedule()marks the function as a CAKE schedule.lmis the builder through which every resource, role, and operation is declared, the way you usenp.ortorch.. Going by their names,Q: LM.tma3dis a 3-D tensor the TMA copy engine reads,O: LM.tma2da 2-D output, andseqlen_q: LM.i32a 32-bit integer;Oandseqlen_qare unused in this fragment. - Resources.
lm.smem(98304)reserves a 96 KB pool of shared memory.pool.view(...)carves out a named buffer of 128 × 128 BF16 values with three stages: three stages × 128 × 128 values × 2 bytes = 96 KB, so the stages fill the pool exactly.lm.tmem(...)reserves a 128 × 128 FP32 accumulator in tensor memory. Nothing here is an address; every buffer has a name, a shape, a type, and a lifetime the compiler can see. - Roles and synchronization.
lm.role(warps=[0])andlm.role(warps=[1])name two warp roles, a loader and a tensor-core issuer.lm.pipeline(stages=3)declares the pipeline, andlm.barrier(...)declares the handoff between them: a barrier whose producer isloadand whose consumer ismma. Our reading of the arguments:count=3gives it one barrier per stage, andinit_count=1is the arrival count, so one arrival (the copy landing) completes each phase. - Work per role.
with load:does not open anything, aswith open(...)would in Python: it means “the code inside runs only on the warps of theloadrole.”lm.rangeis the schedule’s own loop, not Python’srange. Insidewith load:, the loader issues one TMA copy per stage and has the hardware arrive onq_fullwhen each copy lands. Insidewith mma:, the tensor-core warp waits onq_fullfor each stage, callslm.fence_proxy(), and issues the matrix multiply into the TMEM accumulator, initializing it on the first stage. By its name,fence_proxyis a proxy fence (§3.2); the paper does not say what it lowers to, and since the TMA write and the tensor-core read both go through the async proxy, the fragment alone does not show why it is needed here.
Notice what is missing. There are no barrier addresses, no phase bits, no descriptor encodings, and no computation of which thread is in which warp; the compiler derives all of them from the declarations. The buffers do carry a few plain commitments, such as the view’s offset inside the pool and the accumulator’s starting column in tensor memory. §7.3 explains why CAKE asks for those directly, and the compiler derives the rest of the addressing from them. The fragment is a teaching example, not a complete kernel: it multiplies the Q tile by itself, where a real attention kernel would also load K and V and run a softmax.
You may also notice a missing barrier. §3.2 said each stage needs a full and an empty barrier, but this fragment declares only q_full. It fills each of its three stages exactly once and never wraps around the ring, so no slot is ever overwritten. A real main loop that streams many tiles through the ring would also declare an empty barrier, arrived on by mma and waited on by load: exactly the wait whose absence causes the race in the §3 figure.

7.2 Four properties that make it checkable
The paper names four properties that “do the work”:
- Type-checked vocabulary. Compute, memory movement, synchronization, math, and warp control use a fixed set of IR operations, not embedded C or PTX strings. An ill-typed program is rejected while it is being built.
- Declared resources. Memory regions, synchronization objects, and pipelines are declared once, so “the IR knows the shape, dtype, and lifetime of every buffer.”
- Explicit roles. Warp groups are named, and “every cross-role handoff is visible rather than an implicit convention.”
- Auto-derived metadata. The mechanical consequences of the declarations are “lowered, not authored.”
The payoff is that analyses can reason about schedule decisions before code generation, and the harness can tie a finding to the affected resource, role, or stage, “rather than returning only a backend error or a hang.”
7.3 No layout algebra, on purpose
CAKE “deliberately does not make layout a first-class abstraction.” Instead of manipulating layouts as mathematical objects, the agent writes down concrete commitments: “an SMEM view offset, an operand byte offset, a TMEM column range, a swizzle tag, a TMA descriptor coordinate.” The compiler then “carries the burden of deciding whether those commitments are legal”: it checks that they stay consistent along the program’s data flow (what the producer writes is what the consumer expects to read) and that they satisfy the target instruction’s rules. A diagnostic names the IR decision at fault and a broad category of mismatch.
The §7.1 fragment already contains two such commitments: pool.view(offset=0, ...) says the ring starts at byte 0 of the pool, and lm.tmem(cols=0, width=128, ...) says the accumulator occupies tensor-memory columns 0 to 127. A swizzle is a fixed shuffling of where elements sit in shared memory, so that threads reading together do not collide on the same memory bank. If, say, the TMA copy wrote a tile with one swizzle and the MMA read it assuming another, the compiler would point at the disagreeing declaration before anything runs. (The example is ours; the paper describes the checks only by category.)
This is the reverse of CuTe’s bargain. CuTe asks the author to be an expert in layouts and rewards them with expressive power. CAKE asks the author for plain facts and makes the compiler responsible for catching contradictions. The paper describes its layout verifier only by its contract and coverage, not its internals.
7.4 One language, many GPUs
The same schedule language targets NVIDIA GPUs from Ampere through Blackwell. The structure of a role–barrier–pipeline schedule carries over; which instructions are allowed, and how they are lowered, remains specific to each target. (The sm_ names are NVIDIA’s codes for GPU generations: sm_80 is Ampere, sm_90a Hopper, sm_100a Blackwell; the trailing a marks features specific to that chip.) You do not need the details below; the right-hand column just shows the instruction set changing under the same schedule structure.
Which GPUs CAKE targets, and what changes between them
| Target | Example GPUs | Tensor-core path and notable features |
|---|---|---|
sm_80 |
A100 | mma.sync, ldmatrix, cp.async; no TMA, clusters, or TMEM |
sm_89 |
L40S, RTX 6000 Ada | as sm_80, plus FP8 tensor cores; no TMA or TMEM |
sm_90a |
H100, H200 | WGMMA + mma.sync; TMA, clusters, async barriers, distributed shared memory |
sm_100a |
B200 | tcgen05.mma + TMEM; 2-CTA MMA; tcgen05.{ld,cp,shift} |
sm_103a |
B300 | adds tcgen05.ld.red and K = 96 block-scaled MMA |
sm_120a |
RTX 5090, RTX PRO 6000 | mma.sync + ldmatrix, TMA, clusters, distributed shared memory; no tcgen05 or TMEM |
sm_121a |
DGX Spark (GB10) | same instructions as sm_120a, separate binary, different special-function-unit rates |
Two policies stand out. The compiler “requires an exact target match”: it reports a missing device or toolchain rather than quietly lowering a schedule to an older architecture. And performance estimates appear only where they are calibrated: B200 is the measured baseline, H100 is calibrated separately, and other targets report a coverage limitation instead of borrowing numbers. After the static checks, CAKE IR lowers deterministically to readable CUDA/PTX and then through NVIDIA’s standard toolchain. The generated source stays available as an escape hatch; by default, the decisions stay in the IR where they can be analyzed.
8. Where CAKE IR Came From
You might expect a language like this to be designed on a whiteboard and then implemented. CAKE IR was grown instead.
8.1 Grown from expert kernels
“CAKE did not begin with a predefined CAKE IR vocabulary.” Its starting material was a corpus of production kernels and a set of hardware design principles. The appendix describes five steps:
- Corpus collection. High-quality CUDA kernels from production libraries: Alpha-MoE, CUTLASS, cuTile, DeepGEMM, FlashAttention-4, Flash-KMeans, FlashInfer, SonicMoE, and TileLang. Kernels written in other languages were first translated to CUDA with inline PTX by coding agents.
- Abstraction extraction. Agents analyzed the corpus and summarized recurring patterns (barrier choreography, pipeline staging, warp-role partitioning, TMA descriptor setup, TMEM accumulator lifecycles) into candidate abstractions.
- Hardware-informed design. Human expertise steered the abstractions toward the Blackwell programming model: TMEM as a first-class resource, warp specialization as the main form of parallelism, asynchronous barriers as the synchronization primitive, and cluster-scoped operations for coordinating several SMs.
- Principle-driven iteration. Each candidate abstraction was checked against eight design principles (below); violations were refined or rejected.
- Port-driven expansion. New kernels are ported continuously. Each port either succeeds, which validates the abstractions, or reveals a gap, which triggers a proposal to extend the IR or its lowering.
The loop never closes: “every new kernel family stress-tests the IR and drives further evolution.” The design target throughout was demanding: the IR must “reproduce the physical schedules and performance of expert-written kernels.” According to the paper, the harness is likewise “maintained primarily by agents under human merge gates.”
8.2 Eight principles
Each candidate abstraction is checked against these eight principles, summarized from the paper’s appendix:
| Principle | What it asks |
|---|---|
| P1 Ergonomic | Feel familiar to NumPy and PyTorch users; avoid needless bookkeeping. |
| P2 Performance-transparent | Keep performance-relevant hardware decisions visible and lowering inspectable. |
| P3 Canonical | One canonical form per operation, not several equivalent spellings. |
| P4 Statically type-checked | Typing rules constrain lowering and reject ill-typed programs during construction. |
| P5 Analysis-friendly | Expose the information the static analyses need. |
| P6 Test-gated | Evaluate every IR change against the kernel-matrix tests for analysis and compilation. |
| P7 Analysis-consistent | Change the analyses whenever the IR’s data model changes. |
| P8 Hardware-grounded | Document the intended hardware behaviour of every operation. |
P5 and P7 keep new features analyzable, P6 guards against regressions, and P2 and P8 keep the mapping to hardware legible “to humans and agents alike.” The paper connects this to an observation by the mathematician Terence Tao about AI-generated proofs: when generating artifacts becomes cheap, the bottleneck shifts to verifying and understanding them. CAKE’s version: when agents can produce kernels in bulk, what matters is that each kernel can be checked and read.
Summary of Part II
Kernel agents today live in a black box that answers with pass/fail and a time. CAKE gives them a language in which the expert’s decisions (roles, buffers, barriers, pipelines) are explicit and typed, while the error-prone bookkeeping (barrier addresses, phase bits, descriptor encodings, warp identity) is derived by the compiler. It deliberately avoids a layout algebra and makes the compiler check concrete layout commitments instead. The language was grown from production kernels, under eight principles that keep it analyzable as it grows.
Part III · The Loop — a dialogue
Student OK, so the agent writes this schedule language. Then what? It still has to run on the GPU eventually.
Professor Eventually. But a GPU run is the expensive way to find a missing barrier. What's cheaper?
Student Reading the code first? Like a linter?
Professor Exactly: checks that run before compilation and say which barrier, which stage. Then a cost model, a cheap estimate of how fast each survivor would run, picks the ones worth timing. Only then the GPU.
Student And when the checks themselves miss a whole kind of bug?
Professor Then you've found the paper's most interesting idea. The bug becomes a new check. The compiler learns.
Student Does all this actually make faster kernels? Or just nicer error messages?
Professor Good. Keep that skepticism. We'll look at the evidence, and at what it doesn't show.
9. The Harness: Checks Before the GPU
The harness is everything around the agent: the analyses, the tests, the benchmark, and the rules for what counts as a result. This section describes what CAKE’s harness checks and what it says back.
9.1 Seven kinds of checks
The paper describes its analysis suite by what it does for the agent, not by its internal compiler passes. There are seven categories, in three dispositions: gates that reject a candidate, reports that describe it, and hints that suggest improvements.
| Category | Disposition | Purpose | Example (ours, illustrative) |
|---|---|---|---|
| Program safety | pre-compile gate | Find synchronization, ordering, and memory-use hazards | a consumer waits on a barrier no producer ever arrives on (§3.3) |
| Hardware conformance | pre-compile gate | Enforce supported resource, instruction, and architecture contracts | buffers that need more shared memory than the SM has, or a Blackwell-only instruction on a Hopper target |
| Data consistency | pre-compile gate | Check data flow and that producer and consumer agree on representations | the TMA writes a tile with one swizzle and the MMA reads it assuming another |
| Schedule semantics | pre-compile gate | Check the structural invariants of the declared schedule | a three-stage pipeline whose loop touches a fourth stage |
| Numerical validation | execution gate | Compare compiled outputs with an authoritative external reference | the output differs from the reference by more than the tolerance |
| Performance analysis | report | Estimate cost and identify broad bottleneck classes | “probably limited by memory bandwidth” |
| Optimization guidance | hint | Suggest promising revisions without blocking compilation | “a deeper pipeline may hide the copy latency” |
The four pre-compile gates reject “many candidates that are mathematically plausible but incompatible with the target execution model.” A finding “identifies the affected program region and the class of violated contract.” Compare that with the hang from §3.3: instead of a frozen GPU, the agent hears something like the consumer waits on stage 2 of this barrier, but no producer ever arrives there. That example is ours; the paper does not publish its message format.
9.2 Correctness and performance
Numerical correctness is checked against a reference implementation across different shapes and input distributions, and final acceptance requires end-to-end evaluation in the target framework (for example, a full model served by SGLang, a popular open-source LLM serving system).
Performance has two layers. A calibrated cost model estimates how fast a candidate will run and names its likely bottleneck, so the harness can rank and filter candidates without running all of them. But the model is only a filter: “on-device measurement and profiling remain the final ground truth.” In the evaluation, kernel timings are measured on the GPU with CUPTI, NVIDIA’s profiling interface, with the L2 cache flushed before each timed sample so that one run cannot warm the cache for the next. (A few numbers in §13.2 are measured differently: the API-level Alpha-MoE speedups and the SGLang serving throughput.)
The paper is careful about what its static analyses promise. They are a gate “only within its modeled domain”; they do “not prove global GPU correctness or capture all microarchitectural behavior”; “both false positives and false negatives can occur.” Missing information is “reported explicitly rather than treated as a successful check.”
10. One Round of Evolution
With the language and the harness in place, a run of kernel evolution has a simple shape. This section follows one round.
10.1 Four stages
The paper describes a run as four stages:
- Generate structurally distinct CAKE IR candidates: different role splits, pipeline depths, memory placements, not just different constants.
- Filter them with IR construction checks, the verifier’s hard gates, and cost-model ranking, before any GPU time is spent.
- Evaluate the survivors against the external oracle (a trusted reference implementation whose output defines the right answer), with benchmarking and profiler evidence.
- Route the evidence. Depending on the diagnosis, a finding goes back to the candidate (repair it), to the verifier (add a rule), to the cost model (recalibrate it), or to the IR vocabulary (add a primitive).

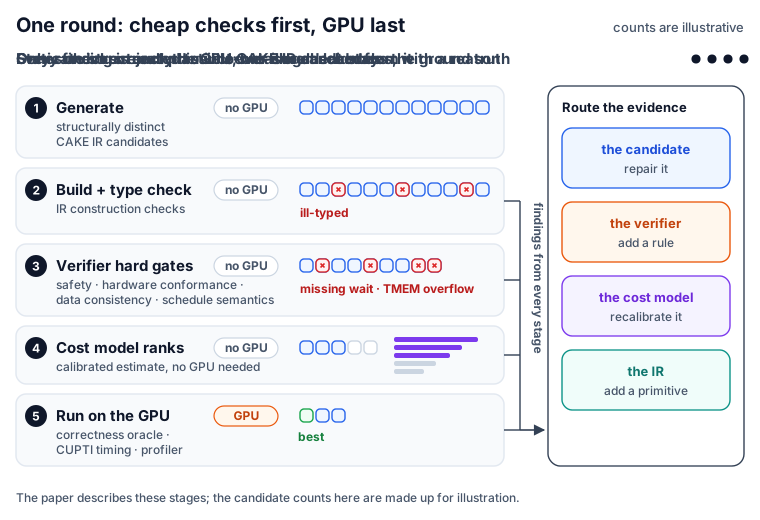
The fourth stage is what makes CAKE different from a search loop with better error messages. A finding is not just used and discarded; it is sent to whichever part of the system should learn from it.
10.2 What stays fixed
Two things anchor every run. The first is the workload contract, the “stable authority”: it fixes the shapes, the correctness oracle and its tolerances (how close to the reference an output must be, as with torch.allclose), the hardware, and which references the agent may see. Results are retained, so decisions can be audited and recurring findings reused.
The second is the model. All agent tasks in the paper use the same model, GPT-5.6-sol, at reasoning effort xhigh. “Holding the model and agent scaffold fixed makes the comparisons … attributable to the environment rather than to model capability.” (The scaffold is the program around the LLM that gives it tools to edit files and run code, and that drives the loop.) Whatever difference shows up between two arms of an experiment, it is not because one had a smarter model.
11. The Compiler Evolves Too
So far, the agent evolves kernels inside a fixed environment that happens to be well designed. CAKE’s last commitment is that the environment is not fixed.
11.1 Two paths into the compiler
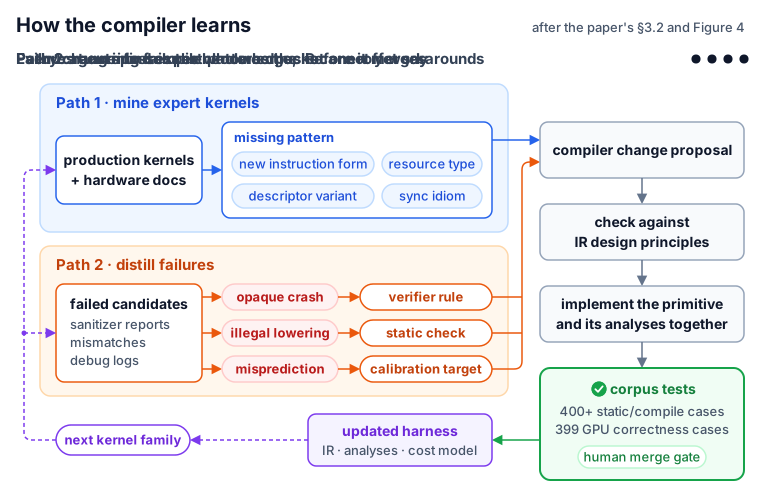
Kernel candidates, validation results, benchmarks, and failure reports are all evidence for changing the compiler. The paper describes two paths:
- Path 1: mine expert kernels. Agents inspect production kernels and hardware documentation to find Blackwell patterns the IR is missing (“new instruction forms, resource types, descriptor variants, synchronization idioms”) and write compiler change proposals. Each proposal is checked against the design principles of §8.2, including performance transparency and friendliness to verification, before it is implemented.
- Path 2: distill failures. Agents use feedback from failed candidates (“sanitizer reports, failure cases, correctness mismatches, debugging logs”) and turn recurring or costly failure modes into new analyses: “an opaque runtime crash becomes a verifier rule, a repeated illegal lowering pattern becomes a static check, a systematic misprediction becomes a calibration target.”

11.2 Why primitives and analyses must change together
The two paths feed each other. A new primitive tells the compiler more about the hardware, which makes stronger analyses possible; a new analysis constrains what future primitives may look like. The paper insists that a primitive and its analyses “must evolve together”: “syntax without effects and legality rules makes the IR less analyzable, and a new verifier rule without corpus validation can reject valid kernels.” In plain terms: add a new operation to the language without telling the checker what it reads, writes, and requires, and the checker goes blind to every program that uses it; add a new check without running it on known-good kernels, and it may start rejecting correct programs.
That is why every compiler change is test-gated across the kernel corpus. The corpus is large: more than 400 static and compile cases and 399 GPU correctness cases, across roughly 28 kernel families (§13.4). A new rule that rejects a known-good kernel does not merge.
Who makes these changes? Agents implement and maintain the analyses from high-level descriptions written by humans, and humans approve merges: the paper says compiler evolution “is still human-guided at merge gates.”
12. The Controlled Experiment: Flash-KMeans from a Clean Start
Descriptions of a system are cheap; a controlled comparison is not. This section covers the paper’s cleanest experiment: the same agent, the same model, the same task, written either in CAKE IR or directly in CUDA/PTX.
12.1 The workload: one step of k-means
k-means is one of the oldest algorithms in machine learning. You have N points and want K groups. Start with K guesses for the group centres (centroids), then repeat two steps: assign every point to its nearest centroid, and update every centroid to the average of the points assigned to it. Each repetition is called a Lloyd iteration.
Flash-KMeans is a fast, exact GPU implementation, and it matters for a reason you might not expect: video generation. Sparse VideoGen2 groups similar tokens with k-means so that sparse attention can work on contiguous blocks of related tokens (“semantic-aware permutation”). There, k-means runs inside the model’s forward pass, so the time it takes is added directly to generation time. (Sparse attention computes attention only for the most important token pairs.)
According to the paper, a Lloyd iteration is dominated by two BF16 kernels that account for more than 95% of the end-to-end time:
assigncomputes the squared distance from every point to all K centroids and returns the index of the nearest one. It is compute-bound: a matrix multiplication followed by a reduction.centroid_updatesums the points of each cluster and counts them. It is limited by memory bandwidth and by contention on atomic updates (many threads adding into the same cluster’s running sum at once, which the hardware must apply one at a time).
The experiment focuses on assign, which “exercises the tensor-core pipeline and scalar epilogue” (here the epilogue picks the nearest centroid), at one fixed shape: B = 32 batches, N = 65,536 points, K = 1,024 centroids, D = 128 dimensions, BF16 inputs and FP32 accumulation. The bar is high: the baseline is a tuned Triton implementation from the FlashML project (whose library, FlashLib, collects fast GPU versions of classical machine-learning operators), measured at 0.938 ms.
12.2 The rules: what the agent may and may not see
The paper is careful about a subtle form of cheating. If the agent could read an expert’s CUDA for this kernel, it could copy the schedule instead of discovering it. So in these clean-start runs the agent may see “the mathematical specification, evaluation contract, correctness oracle, and high-level code, but not low-level target implementations such as CUDA, PTX, SASS, or equivalent generated source.” (SASS is the GPU’s actual machine code, one level below PTX.) An existing implementation may be run as a black-box timing baseline, but its internals stay hidden. The restriction was enforced in isolated environments and audited afterward.
The two arms differ in what the agent writes, and therefore in the compiler feedback it gets back:
- Treatment: the agent writes typed CAKE IR, with the harness of Part III.
- Control: the agent writes CUDA C++ and inline PTX directly, under the same reference rules.
Everything else is fixed: the coding agent and its scaffold, the model and reasoning effort, the task statement, the correctness oracle, the benchmark harness, and the target shape. Each arm runs three times, with a budget of 80 million tokens.
12.3 The result
Table 2 of the paper gives the outcome at the full 80M-token budget, three runs per arm:
| Representation | Reached a plateau by 80M tokens | Active evolve time (hours) | Best speed at 80M tokens (× baseline) |
|---|---|---|---|
| CAKE IR | 3 of 3 runs | 1.89 [1.02, 2.33] | 1.144 [1.041, 1.205] |
| Direct CUDA/PTX | 0 of 3 runs | 3.73 [3.59, 4.34] | 0.928 [0.852, 1.151] |
Entries are medians over three runs, with [minimum, maximum] in brackets. With CAKE IR, the median best kernel runs 14.4% faster than the tuned baseline (1.144×); with direct CUDA/PTX, it runs at 92.8% of the baseline’s speed. CAKE IR runs met the paper’s “prespecified plateau criterion” in all three runs; the CUDA/PTX runs met it in none. A run reaches a plateau when its best speed has stopped improving, by a rule the paper fixed in advance but does not publish. So all three CAKE runs had leveled off by 80M tokens, while all three CUDA/PTX runs were still improving when the budget ran out, and we cannot say where they would have ended. The CAKE runs also used about half the active time; since the paper does not break that time down (its stopping and timing accounting is “retained in the artifact”), we cannot tell whether they finished sooner because they stopped at a plateau or because each step was quicker.

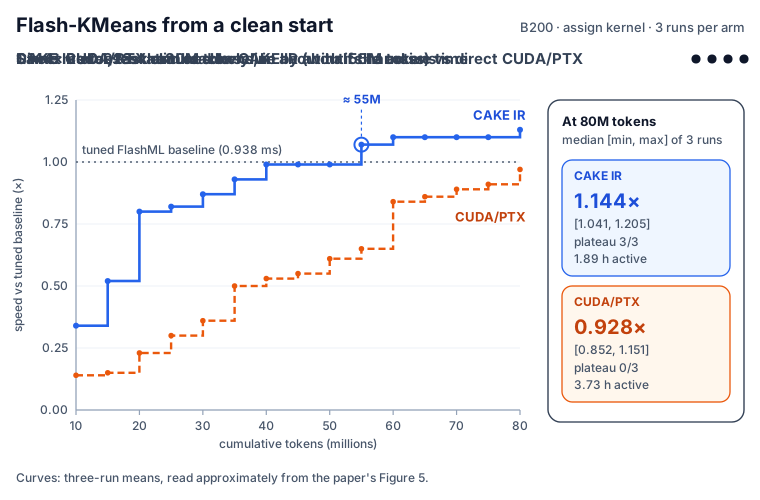
The trajectory tells the same story over time. At each 5-million-token checkpoint, every run contributes its best validated speed so far. The mean of the CAKE IR runs “crosses the tuned FlashML baseline by 55 million tokens and continues to improve, while the direct CUDA/PTX mean remains below baseline at the 80-million-token cutoff.” Reading the paper’s plot (approximate values), the CAKE IR mean is already near 0.8× by 20M tokens, when the CUDA/PTX mean is still around 0.2×.
12.4 How to read it
Our interpretation, with the caveats the numbers themselves carry:
- Within the same budget, the environment changed the outcome. With CAKE IR and its harness, all three runs beat a tuned baseline; the CUDA runs, on median, did not, and they were still climbing. Which part of that environment did the work (the language, the checks, the cost model, or compiler evolution) is still open (§16.2).
- But direct CUDA is not hopeless. The best CUDA/PTX run reached 1.151×, above the CAKE median. The difference is consistency and pace: CUDA can get there, but less reliably and more slowly. With three runs per arm, the spread matters as much as the median.
- It is one kernel, at one shape, with one model. The experiment isolates the effect of the environment well, but it does not tell us how large the effect is for other kernels or other models.
13. Beyond the Benchmark
The controlled experiment shows the effect cleanly; the rest of the evaluation shows the system at work on real kernels. It answers two more questions: can CAKE discover a kernel’s schedule when it may not look at any existing low-level implementation (fast ones may exist, but only as black-box timing baselines), and can it reproduce, or beat, kernels that experts already tuned?
13.1 Frontier kernels: new architectures, no reference to copy
The paper calls a kernel frontier “in the operational sense that the agent must discover its physical schedule without inspecting a low-level target implementation.” This is where a co-evolving IR should help most, and also where it is most exposed: a missing capability shows up as a schedule “the agent cannot express at all.”
Kimi Delta Attention. The official FlashKDA kernels served only as a black-box timing baseline; their source and generated code were not given to the agent. The agent-generated prefill kernel, compatible with FlashKDA and covering fixed-length, packed variable-length, and tail inputs (batches whose sequences share one length, batches of different-length sequences packed end to end, and the leftover tokens at the end of a sequence), reaches a 2.05× geometric-mean speedup over that baseline across six B200 BF16 shapes. The paper calls it “bitwise correct on its validation contract” (the pull request itself reports outputs that match FlashKDA within a tolerance of 10−2), and it was verified in end-to-end serving of Kimi-K3 under SGLang. Separate decode kernels reach a 1.14× geometric-mean speedup over upstream FlashInfer (the library’s current official kernels) across 30 public-API shapes. Both went into FlashInfer, an open-source kernel library used inside LLM serving engines such as SGLang and vLLM, as generated CUDA (pull requests #4262 and #4279, merged in August 2026), “so downstream users take on no dependency on CAKE.”
Gated DeltaNet and sparse attention. Against FlashInfer, CAKE’s Gated DeltaNet prefill and speculative-decoding paths “improve performance while preserving the model’s recurrent state,” and MiniMax sparse attention shows that the representation supports sparse-attention families across prefill and decode. The paper gives no speedup numbers for these two. They are “dispatch families rather than single kernels”: several physical schedules, each its own CAKE IR program, behind one entry point (§14).
13.2 Production kernels, evolved from a reference
TinyGEMM. Here the agent starts from an existing kernel: FlashInfer’s BF16 matrix multiply for tiny batches (the paper calls it small-M), derived from TensorRT-LLM, NVIDIA’s own LLM-inference library. Tiny batches are typical when a server decodes a handful of requests at once. The agent produced an adaptive family of shallow and deep pipelines, including variants that use programmatic dependent launch (PDL, which lets the next kernel start its preamble before the previous one finishes) and paths for batch sizes below eight. FlashInfer PR #4274 reports an 18–23% geometric-mean reduction in kernel time across 35 canonical shapes and a broader regression suite. Greedy decoding (always taking the single most likely next token) produced bit-for-bit identical outputs for GPT-OSS-20B and GPT-OSS-120B on B200 and on GB300, a newer Blackwell system. An SGLang experiment with GPT-OSS-120B measured up to 7.6% more output tokens per second with 128 requests in flight on one GPU, and no difference beyond noise when the model was split across four GPUs (four-way tensor parallelism).
Alpha-MoE. In a mixture-of-experts layer, a small router sends each token to a few of many “expert” feed-forward networks and weights their answers. The original Alpha-MoE does the whole layer in one GPU program, a megakernel, written for Hopper with 8-bit weights and activations (W8A8). CAKE agents rewrote it for Blackwell. The megakernel gathers the tokens routed to each expert, runs the expert’s two matrix multiplies with the activation function between them, converts the intermediate result back to 8 bits (requantization), and adds each expert’s output into its token’s result, weighted by the router’s score. Against FlashInfer’s TensorRT-LLM-derived pre-routed API, the end-to-end API-level speedups are 6.204× at N = 256 and 4.025× at N = 512; measured as GPU span, they are 1.215× and 1.170×. (The paper does not say what N counts here; it is not the N of the k-means experiment.) The kernel was merged into FlashInfer in September 2026 (PR #4287), but the pull request reports a different comparison: against stock SGLang’s five-kernel Triton MoE path on GB300, its fused kernel is 1.37×–1.75× faster in GPU time. The paper’s 6.204× and 4.025× do not appear there.
13.3 Reproducing expert kernels
The last question is whether, when expert structure already exists and the agent may look at it, the harness helps agents preserve correctness while matching highly optimized kernels. The references come from FlashAttention-4, TensorRT-LLM, DeepGEMM, CUTLASS, and FlashInfer. All runs are on B200 at a fixed shape, use median CUPTI GPU span, and pass kernel-specific correctness gates. You do not need the variant names: read “Relative performance” (above 1.0× means CAKE’s kernel is faster than the expert’s) and compare the line counts (“device” lines are the code that runs on the GPU).
| Family | Variant | Relative performance | CAKE IR lines | Reference device lines |
|---|---|---|---|---|
| FlashAttention-4 | forward, BF16, non-causal | 1.0045× | 430 | 2,369 |
| FlashAttention-4 | backward, BF16, non-causal | 1.0470× | 514 | 2,552 |
| TensorRT-LLM GQA | decode, FP16 | 1.043× | 783 | 8,515 |
| DeepGEMM | 1D1D GEMM, FP8 | 1.0370× | 221 | 516 |
| DeepGEMM | grouped GEMM, BF16, masked | 1.0174× | 401 | 442 |
| DeepGEMM | MQA indexer, FP8 | 1.2700× | 480 | 704 |
| DeepGEMM | MQA indexer, FP4 | 1.2730× | 392 | 704 |
| DeepGEMM | paged MQA indexer, FP4 | 1.0036× | 395 | 779 |
| CUTLASS MLA | decode, BF16, TMA | 1.2174× | 845 | 1,860 |
| DeepSeek-V4 sparse MLA | decode, BF16 | 1.1297× | 1,299 | 13,609 |
| DeepSeek-V4 sparse MLA | decode, FP8 | 0.9649× | 1,393 | 8,942 |
Ten of the eleven comparisons meet or beat the reference; the last reaches 96.5%. The paper adds two honest qualifications. Entries below the reference “generally reflect compiler-integration maturity”: a feature the kernel wants is still being integrated into the compiler, so the submitted kernel uses the closest supported strategy. And the strongest wins, the two MQA indexers at about 1.27×, “are not faithful transcriptions of the reference kernels”: the agent explored optimizations the original lacked, so above-parity results “reflect search rather than transcription fidelity alone.” The line counts are descriptive only; the languages and counting scopes differ, and they show just that these schedules “can be represented compactly.”
Shapes and counting details
- S1 (FA4): B = 4, H = 32, S = 8,192, D = 128. S2 (TRT-LLM GQA): B = 128, 64 query heads, 8 KV heads, KV length 4,096, D = 128, page size 16. S3 (FP8 GEMM): M = 4,096, N = 7,168, K = 4,096. S4 (grouped GEMM): 256 groups × M = 128, N = 4,096, K = 7,168. S5 (MQA indexers): H = 32, D = 128, query length 1,024, KV length 2,048. S6 (paged indexer): B = 256, H = 64, D = 128, average KV 4,096, block 64. S7 (CUTLASS MLA): DeepSeek-V3, B = 128, KV length 4,096, page 128. S8 (DeepSeek-V4 sparse MLA): B = 3, ragged query lengths [3, 4, 5], H = 128, Dqk = Dv = 512.
- The paper’s table also lists “reference + support” line counts (for example 3,039 and 3,690 for the two FA4 kernels). For DeepSeek-V4, reference lines are restricted to source reachable under the fixed S8 route and runtime constants.
- GQA (grouped-query attention) lets several query heads share one key/value head; “causal” attention lets a token look only at earlier tokens. MQA (multi-query attention) indexers score which past tokens a query should attend to, as in DeepSeek-V3.2’s lightning indexer; MLA is DeepSeek’s multi-head latent attention. “Paged” kernels read a KV cache stored in fixed-size blocks. Our GLM-5.3 and DeepSeek-V4 deep dives explain both.
13.4 The breadth of the corpus
The headline experiments hide how much the harness now sustains. The validated corpus contains more than 400 static and compile cases and 399 GPU correctness cases across roughly 28 families, including attention, dense and sparse GEMM, MoE, quantization, normalization, state-space models, KNN (k-nearest-neighbour search), and KMeans, with architecture-specific paths from Ampere through Blackwell. It includes more than 100 ports of TensorRT-LLM kernels for attention, MLA decode, and MoE.
One property stands out: composition. Because roles, barriers, and buffers are declared rather than implied, schedules that would normally be separate kernels can be written as one device program. BatchAttention combines decode and prefill work in one kernel; the Alpha-MoE and mega-MoE families fuse routing, expert computation, and output accumulation “without materializing intermediate results” (that is, without writing them out to memory). The Alpha-MoE rewrite also shows that “schedule structure can survive even when target instructions change,” from Hopper’s to Blackwell’s.
14. From a Tuned Shape to a Library
Everything so far optimizes a kernel for a particular shape. A library has to accept whatever shape the caller passes. This section covers the step that benchmark papers usually skip, and that CAKE treats as a stage of its own.
14.1 A different objective, so a separate stage
“Closing that gap is not a matter of running the inner loop on more shapes; it is a separate stage with a different objective, a different ranking signal, and a different failure mode.” An exact shape gives evolution a clean target and permits aggressive specialization; scoring the inner loop on broad coverage would blur that signal. So generalization begins only after strong per-shape seeds exist, and it is scored on performance including the dispatcher over a fixed workload. Incorrect or slow seeds go back to the inner loop “rather than being hidden behind routing.”
14.2 Building a dispatcher
A dispatcher is a small piece of code in front of several kernels that looks at the input shape and calls the right one. In Python it would be an if/elif/else chain (an illustrative sketch, not CAKE’s code):
def kmeans_assign(x, centroids):
    D = x.shape[-1]
    if D == 352:
        return split_k_d352(x, centroids)
    elif 144 <= D <= 176:
        return padded_tail(x, centroids)
    # ... more routes ...
    else:
        return fallback(x, centroids)
Each condition is a guard, each kernel behind one is a route, and the final else is the fallback. (“Split-K” splits the long reduction dimension across several thread blocks and adds up their partial results, which helps when the other dimensions are too small to fill the GPU; a “padded tail” route rounds an awkward size up to a convenient one.)
The generalization stage groups the measured seeds into shape buckets, produces specialized or shared variants, and orders their guards (conditions on the shape, such as “D = 352”) behind an explicit fallback that handles anything the guards do not match. Tuning may change implementation parameters, but never the input shape. Before any aggregate number is reported, validation covers representative and held-out inputs, boundary and tail cases, guards that overlap or leave gaps, and the fallback path itself.

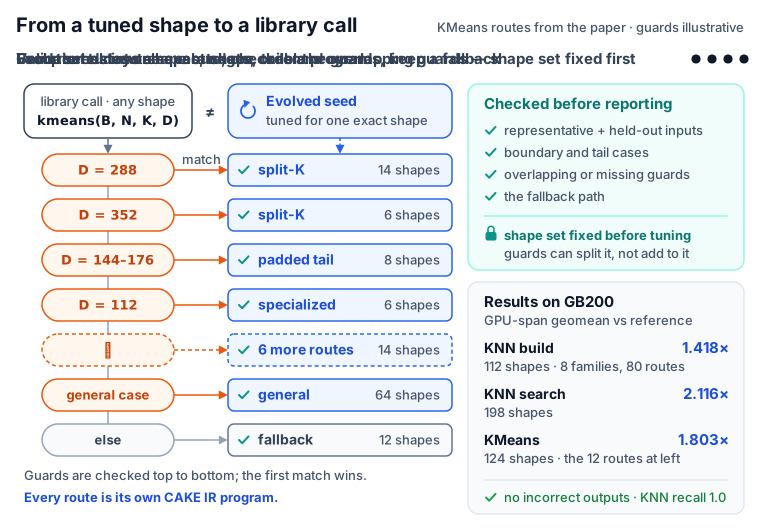
One policy keeps routing from turning into a zoo: the stage “reuses a single physical schedule across as much of the shape domain as it can, and introduces another only when the domain requires a material schedule change.” Each route is its own CAKE IR program, so every alternative can still be analyzed and benchmarked on its own.
14.3 Not grading your own homework
The subtle danger in this stage is evaluation leakage: if the same shapes are used to tune the dispatcher and to report its speed, the dispatcher can simply memorize them. CAKE declares the valid shape domain before tuning. Dispatcher predicates “may partition that domain, but they may not introduce convenient new evaluation rows,” and coverage expands only “through deterministic unseen shards of the same source”: new test shapes are drawn by a fixed rule from the same source and kept unseen during tuning.
14.4 Results on real libraries
The classic machine-learning workloads give the cleanest reading, because their portfolios are too large for one shape to carry the result. KNN (k-nearest neighbours) finds, for each query point, the closest points in a data set: “KNN build” usually means computing it among all points of one set (building a neighbour graph), “KNN search” for separate query points. On GB200, the generalized KNN build, KNN search, and KMeans kernels that CAKE contributed to FlashLib (merged in August 2026 as pull requests #15, #16 and #18; the paper itself cites no PR numbers) reach these results in the paper’s measurements, where Gspan is the unweighted geometric mean, over shapes, of the reference’s median CUPTI GPU span divided by CAKE’s:
| Library function | Shapes | Gspan |
|---|---|---|
| KNN build | 112 | 1.418× |
| KNN search | 198 | 2.116× |
| KMeans | 124 | 1.803× |
There were no incorrect outputs, and KNN recall was 1.0 (every true nearest neighbour was found). The paper warns against comparing these numbers with the clean-start experiment of §12: the measurements “use different hosts, shape distributions, baselines, and protocols,” so the difference “is not, by itself, a measured cost of generalization.”
Route-level breakdown (the paper's appendix figure)
KNN build (baseline FlashLib 0.2.0): 8 outer families covering 112 shapes, with 80 distinct final routes observed.
| Outer family | Shapes / routes | Gspan |
|---|---|---|
| D64 | 7 / 5 | 1.130× |
| D128 low-K BF16 | 38 / 17 | 1.258× |
| D128 low-K FP16 | 1 / 1 | 1.353× |
| D128 mid-K | 32 / 30 | 1.425× |
| D128 large-K | 10 / 5 | 1.909× |
| D192 | 1 / 1 | 1.432× |
| D256 | 8 / 8 | 1.386× |
| high-D | 15 / 13 | 1.758× |
Flash-KMeans (baseline: the authors’ tuned FlashLib implementation): 12 final routes covering 124 shapes.
| Final route | Shapes | Gspan |
|---|---|---|
| gap-fused general | 64 | 1.753× |
| D288 split-K | 14 | 2.227× |
| aligned-shape fallback | 12 | 1.439× |
| D144–176 padded tail | 8 | 1.786× |
| D112 specialized | 6 | 1.414× |
| D352 split-K | 6 | 3.757× |
| D480 split-K | 6 | 2.597× |
| micro-D hybrid | 2 | 1.309× |
| micro-D pipelined | 2 | 1.095× |
| large paired | 2 | 1.217× |
| D128 specialized | 1 | 1.036× |
| D224 TMEM | 1 | 1.037× |
Values are per-row geometric means from same-session CUPTI measurements.
CAKE touches four research areas: GPU languages (§6), compilers, kernel agents, and self-improving systems. The cleanest way to place it is to ask of each line of work: what gets evolved, and what stays fixed?
| Line of work | Examples | What changes | What stays fixed |
|---|---|---|---|
| Kernel agents with search or memory | KernelEvolve, EvoEngineer, AVO, K-Search, KernelBlaster | the search process, the accumulated memory | the language and the evaluation environment |
| Kernel models trained with RL | AutoTriton, CUDA Agent | the model’s weights | the language and the evaluation environment |
| LLM-driven program search | FunSearch, AlphaEvolve | the programs, through LLM-written mutations | the evaluator |
| Self-improving agents | ADAS (Automated Design of Agentic Systems), Darwin Gödel Machine, Meta-Harness | the agent’s own code, or the code around a fixed model | the foundation model |
| CAKE | the compiler harness: IR vocabulary, analyses, cost calibration | the coding agent and the model |
In the paper’s words, CAKE “targets that complementary layer: it changes the representation being searched and the structured compiler evidence returned to the agent.” Nothing stops the two from combining: a stronger search procedure or a better-trained model could run inside CAKE’s environment.
On the compiler side, TVM, XLA, MLIR, TensorIR, Ansor, and MetaSchedule structure programs so they can be analyzed and optimized automatically, and Graphene, Twill, and Tawa model asynchronous GPU execution, pipelining, or warp specialization. CAKE “shares the principle that structured programs enable useful analysis, but places compiler findings inside an agent evolution loop and lets recurring kernel evidence evolve the harness.” More broadly, the paper cites the “self-defining systems” agenda, which considers AI-operated systems that can change their own mechanisms and abstractions, and then separates CAKE from all of these evolving systems by what is evolved: the agent and model stay fixed, and only a domain-specific compiler harness changes, under corpus tests and human merge gates.
16. Limits and Open Questions
A good paper says where it stops. CAKE does, and a careful reader can add a few more questions.
16.1 What the paper says about its own limits
- NVIDIA only. CAKE targets Ampere through Blackwell. The schedule language, role model, and analyses carry across those generations, but instruction forms, legality rules, and cost anchors are architecture-specific, and “that cost is the honest measure of transfer.” For non-NVIDIA hardware it “remains unmeasured,” and the backend would have to be rebuilt.
- Uneven evidence. Most performance results are on B200. The timing model is calibrated only for B200 and H100 and “declines to predict elsewhere.”
- Incomplete analyses. The static analyses and performance models are intentionally incomplete; they rank and filter, and GPU execution stays the ground truth.
- Humans in the loop. Compiler evolution is “still human-guided at merge gates.”
16.2 Questions the paper leaves open
These are ours, not the paper’s:
- Can others use it? The paper does not say that CAKE’s compiler, IR, or harness is publicly released, and we found no release as of October 2026 (only unofficial community re-implementations). The generated code is public: the four FlashInfer pull requests and three FlashLib pull requests are merged, and a FlashInfer tracker issue indexes many more CAKE-generated kernels.
- How general is the controlled result? The clean-start comparison is three runs per arm, one kernel, one shape, and one model (GPT-5.6-sol). We do not know how the gap changes with other kernels, other models, or a larger budget. (The FlashInfer tracker describes CAKE-generated kernels produced with Claude and Codex agents, which suggests the harness is not tied to one model, but no controlled comparison is reported.)
- Which part does the work? The language, the pre-compile checks, the cost model, and compiler evolution all change at once between the two arms. There is no ablation that, for example, keeps CAKE IR but removes the cost model, or freezes the compiler.
- Why not a tile-language arm? The control arm writes CUDA/PTX. A third arm writing Triton or CuTe DSL under the same rules would show where tile languages and layout algebras land.
- What does compiler evolution cost? The paper does not report how many compiler changes were made, how many came from each path, how often the corpus gate rejected a change, or how much human review the merge gates took.
- How accurate are the checks? False-positive and false-negative rates for the verifier, and the accuracy of the cost model’s predictions, are not reported.
- Missing numbers, and two mismatches. The Gated DeltaNet and MiniMax sparse-attention results are described without speedups, and the plateau criterion is not defined in the text. Two upstream records also differ from the paper: the merged Alpha-MoE pull request reports a different baseline and different speedups (§13.2), and the KDA prefill pull request reports agreement within a tolerance where the paper says “bitwise correct.”
None of these undercuts the main idea. They mark where the next paper, or an independent reproduction, could add the most.
Summary of Part III
CAKE’s harness checks a schedule before it reaches the GPU (program safety, hardware conformance, data consistency, schedule semantics), ranks the survivors with a calibrated cost model, and treats on-device measurement as ground truth. Each round sends its findings to the candidate, the verifier, the cost model, or the IR, and recurring failures become new checks or primitives that must pass the whole kernel corpus behind a human merge gate. With the model fixed, CAKE IR and its harness beat direct CUDA/PTX in a small controlled study, produced new kernels for architectures such as KDA without seeing low-level implementations, matched or beat ten of eleven expert kernels, and turned single-shape seeds into dispatcher-backed library families. The open questions are about generality, attribution, and cost, not about whether the idea works.
Epilogue — a dialogue
Professor So. What did you learn?
Student That a fast kernel is mostly a good schedule: who loads, who multiplies, how they hand tiles to each other, and where every byte lives.
Professor And why agents struggled to write one?
Student They were writing in a language that either hid the schedule or made them manage every address by hand. And all they heard back was "crashed" or a number.
Professor And CAKE's fix?
Student A language where the decisions are explicit and the bookkeeping is derived, checks that name the broken barrier before the GPU ever runs, and a compiler that turns repeated failures into new checks. The agent gets better because its world gets better.
Professor And what would you still want to know?
Student Whether it holds with other models and other kernels, which piece matters most, and whether I can try it myself.
Professor Good. Now you're reading papers properly.
Summary
- The problem. Expert GPU kernels are distinguished by their schedule (warp roles, barrier choreography, memory placement), and mistakes in a schedule cause silent wrong answers or hangs. Kernel agents have improved their search, memory, and models, but they still write in languages that either hide the schedule or expose it without guardrails, and they get back only errors, pass/fail results, and timings.
- The idea. Co-design the agent’s environment with the agent. Agents write CAKE IR, a typed, hardware-explicit schedule language with no layout algebra, in which resources, roles, and handoffs are declared and the mechanical details are derived. A harness checks safety, hardware conformance, data consistency, and schedule semantics before compilation, ranks candidates with a calibrated cost model, and treats GPU measurement as ground truth. The compiler evolves: recurring failures and newly found expert patterns become verifier rules, primitives, and calibrations, gated by a corpus of more than 400 static and compile cases and 399 GPU correctness cases.
- The evidence. With the model fixed, CAKE IR with its harness beats direct CUDA/PTX on a clean-start Flash-KMeans task (median 1.144× vs 0.928× of a tuned baseline at 80M tokens; 3/3 vs 0/3 runs plateaued; about half the active time). Without seeing any low-level implementation (CUDA, PTX, or SASS), it produced a KDA prefill kernel 2.05× faster than the official kernels (geometric mean over six shapes), validated in end-to-end serving. It matches or beats 10 of 11 expert kernels, and its dispatcher-backed KNN and KMeans families are faster by 1.42× to 2.12× (geometric means per family) across more than 400 shapes. Four kernels are merged into FlashInfer.
- The limits. NVIDIA GPUs only, mostly B200 evidence, a small controlled study, incomplete analyses by design, human merge gates, and no public release of CAKE itself (its generated kernels are public).
Questions to Ponder
OSTEP ends its chapters with homework. Ours has no simulator, but these are worth a few minutes each:
- In §3.2, a ring buffer with three stages uses a one-bit phase per barrier. Why is one bit enough? What would go wrong if the producer could run two full laps ahead of the consumer?
- CAKE refuses to step a schedule down to an older GPU (§7.4). What could go wrong if a Blackwell schedule were silently lowered to Hopper instructions?
- The pre-compile checks are allowed to have false positives (§9). In an evolution loop, which is worse: a check that wrongly rejects 5% of valid kernels, or one that misses 5% of broken ones? Does your answer change for a production compiler?
- Design the missing ablation from §16.2: which arms would you run to separate the effect of the language from the effect of the harness and of compiler evolution, and what would each arm keep fixed?
- §14.3 forbids the dispatcher from adding its own evaluation shapes. Give a concrete example of how a dispatcher could look 2× faster than it is if this rule were broken.
- The paper borrows Terence Tao’s point that cheap generation shifts the bottleneck to verification and understanding (§8.2). Where else in machine-learning systems do you see the same shift happening?
Sources and Further Reading
The paper
- CAKE: Compiler–Agent Co-Design for Frontier Kernel Evolution (arXiv:2608.12629), Zihao Ye, Yingyi Huang, Hongyi Jin, Bohan Hou, Junru Shao, Zhongming Yu, Jinqi Chen, Meghan Cowan, Shiyi Cao, Shanli Xing, Hanfeng Chen, Vinod Grover, Tianqi Chen, and Luis Ceze (NVIDIA and Carnegie Mellon University). Every number in this post comes from here unless marked otherwise. Read the paper’s §2–3 (program representation and compiler harness) for the design, and its appendix for the eight principles and the full kernel tables.
The upstream kernels
- FlashInfer pull requests #4262 (KDA prefill), #4279 (KDA decode), #4274 (TinyGEMM), and #4287 (Alpha-MoE), all merged: generated CUDA you can read without CAKE. The CAKE kernel tracker lists many more.
- FlashLib pull requests #15, #16 and #18: the dispatcher-backed KNN and KMeans kernels of §14.
Background on GPUs and kernels
- FlashAttention (Dao et al., NeurIPS 2022): the clearest demonstration that a better schedule, not new math, can make a core operation several times faster. Its successors, through FlashAttention-4 for Blackwell, are a history of GPU features in miniature.
- CUTLASS and CuTe DSL: NVIDIA’s templates for expert kernels, and the layout algebra CAKE chooses not to use.
- Triton (Tillet et al., MAPL 2019): the tile-based language that made kernel writing accessible.
- TVM (Chen et al., OSDI 2018): the compiler that popularized separating what a tensor program computes from how it is scheduled.
Kernel agents and evolutionary search
- KernelBench (arXiv:2502.10517): the benchmark that set up the “PyTorch operator in, fast kernel out” task.
- KernelEvolve (arXiv:2512.23236): agentic kernel coding for heterogeneous accelerators at Meta (the author of this blog is a co-author).
- AlphaEvolve and FunSearch (Nature, 2023): LLM-driven evolutionary program search.
- AVO, K-Search, KernelBlaster, CUDA Agent, and EvoEngineer: recent kernel agents with different ideas about search, planning, memory, and training.
The workloads
- Flash-KMeans (arXiv:2603.09229) and Sparse VideoGen2 (arXiv:2505.18875): the k-means workload and why video generation needs it.
- Kimi Linear (arXiv:2510.26692), Kimi-K3, and Gated DeltaNet (ICLR 2025): the linear-attention architectures behind the frontier kernels.
- Alpha-MoE and FlashInfer: the fused MoE megakernel CAKE rewrote, and the kernel library that received the results.
The writing style
- Operating Systems: Three Easy Pieces by Remzi H. Arpaci-Dusseau and Andrea C. Arpaci-Dusseau, free online. The dialogues, crux boxes, asides, and tips in this post are borrowed, with gratitude, from its format.
On this blog
- GLM-5.3 and GLM-5.3-Flash, Layer by Layer and DeepSeek-V4 and V4-Flash, Layer by Layer: the attention variants (MLA, the lightning indexer, KDA) whose kernels appear in §13.
- Miles v0.1 Deep Dive: another systems paper read closely, on reinforcement-learning infrastructure.
来源:Hacker News · gangliao.me